
PrismMLLanguage modelOpen source

Ternary Bonsai 2 27B

Ternary Bonsai 2 27B has no overall index value yet because there are too few independent benchmark results. From the vendor-reported results we estimate about 72.8 points (95% range 52.4 to 93.1). This is not an independent measurement.

Popularityno data yet

n/ano search or usage data

Summary

Ternary Bonsai 2 27B compresses Qwen3.8-27B into ternary weights. According to PrismML, the densely packed PTQ1_0 files need 5.95 GB for the language model and store 1.75 bits per weight. A separately supplied vision component is added for image input.

The full checkpoint has 27.36 billion parameters and handles 262,144 context tokens. It retains the base model’s architecture. PrismML releases the weights under Apache 2.0, with the idealized ternary precision of 1.72 bits differing from the shipped PTQ1_0 format.

Ternary Bonsai 2 27B in our own test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Ternary Bonsai 2 27B

API request failed. The model was not evaluated.

Earlier tests

This is the lowest documented setting for each provider. It does not make compute comparable across models.
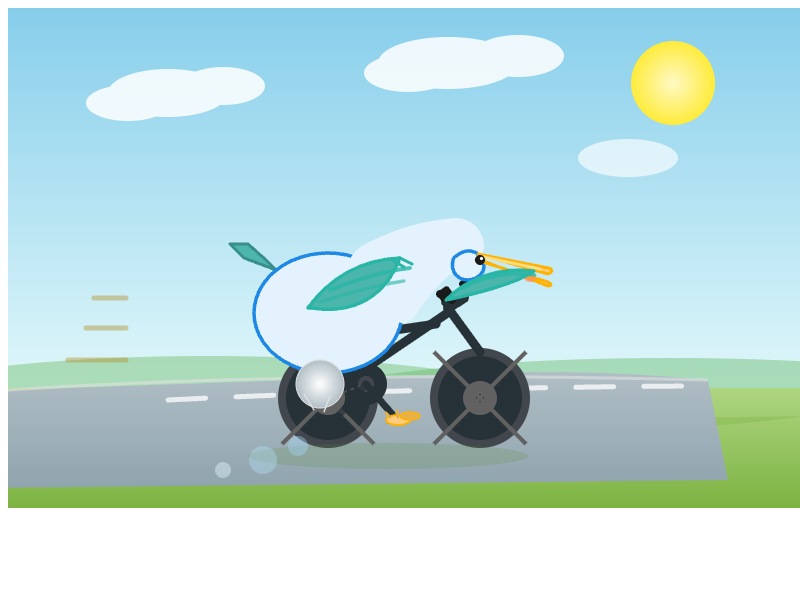
Ternary Bonsai 2 27B: Pelican on a bicycle
A community classic for free-form SVG drawing.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 11, 2026 · 104 s · $0.0022

Test details
Run date
Oct 11, 2026
API provider
Darkbloom
Requested API model
prism-ml/ternary-bonsai-2-27b
Reasoning setting
disabled (enabled: false)
Token limit including reasoning
8,192 tokens
Reasoning tokens
0
Output tokens
4,427 tokens
Cost of the attempt
$0.0022
Response time
103.8 s
API model reported in response
prism-ml/ternary-bonsai-2-27b
Pinned endpoint
Darkbloom | prism-ml/ternary-bonsai-2-27b-20260918
Temperature
Provider default
Test protocol
community-visual-low-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Task origin: Simon Willison

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 67 published benchmark results

Page 1 of 6

Measurements without matching peer values

These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.

MMLU-Redux (Show measurement, test conditions, and source)
Source value
89.09
Metric
MMLU-Redux
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
GPQA Diamond (Show measurement, test conditions, and source)
Source value
85.76
Metric
GPQA Diamond
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
GSM8K (Show measurement, test conditions, and source)
Source value
96.66
Metric
GSM8K
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
AIME25 (Show measurement, test conditions, and source)
Source value
95
Metric
AIME25
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
AIME26 (Show measurement, test conditions, and source)
Source value
95.83
Metric
AIME26
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
HumanEval+ (Show measurement, test conditions, and source)
Source value
95.12
Metric
HumanEval+
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
LiveCodeBench v6 (Show measurement, test conditions, and source)
Source value
90.07
Metric
LiveCodeBench v6
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
IFEval (Show measurement, test conditions, and source)
Source value
91.31
Metric
IFEval
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
IFBench (Show measurement, test conditions, and source)
Source value
74
Metric
IFBench
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
tau2-Bench (Show measurement, test conditions, and source)
Source value
80.22
Metric
tau2-Bench
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
BFCL v3 (Show measurement, test conditions, and source)
Source value
74.92
Metric
BFCL v3
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology
OCR Bench v2 (Show measurement, test conditions, and source)
Source value
56.88
Metric
OCR Bench v2
Unit
%
Category
source-specific
Direction
Higher is better
Source type
vendor-reported
Evaluator
PrismML whitepaper Tables 7, 8, 10 and methodology
Status
active
Retrieved at
2026-10-04
Methodology
Vendor-reported result. NVIDIA H100, EvalScope + vLLM, TP2/DP4, thinking mode, xhigh, top-p 0.95/top-k 20, temperature 1.0, reasoning parser strips thought block. Most tasks single-pass; GPQA mean 5 samples/question; AIME25/26 mean 8/problem; vision tower loaded for vision tasks. Twenty-benchmark suite plus Terminal-Bench 2.1 and SWE-Bench Verified.
Context
Source-specific observation; it is not a shared comparison cohort. PrismML-run EvalScope/vLLM comparison; common harness across baselines and Bonsai, not external leaderboard
Source PrismML whitepaper Tables 7, 8, 10 and methodology

Page 1 of 6

All specifications

Architecture

Base model
Qwen3.8-27B
Source: Base model

Input and output

Context window
262,144 tokens
Source: Context window

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Release
September 17, 2026
Source: Release
License
Apache 2.0
Source: License
Shutdown
None announced
no source

Further details

Compression
PTQ1_0 files at 1.75 bits per weight and a 5.95 GB file size
Source: Compression

Frequently asked questions about Ternary Bonsai 2 27B

How good is Ternary Bonsai 2 27B in benchmarks?

Independent results are not yet enough for the overall index. An estimate from 5 vendor-reported results (AIME 2025 95%, GPQA Diamond 85.8%, LiveCodeBench v6 90.1%, SWE-bench Verified 60.8%, Terminal-Bench 2.1 52.8%) gives about 72.8 points, with a 95% range of 52.4 to 93.1. The estimate is calibrated on models with both vendor-reported and independent results. Vendor numbers run clearly above independent measurements on some tests; the calibration offsets that on average.

Vendor estimate, not an overall index value

How large is the context window of Ternary Bonsai 2 27B?

262,144 tokens. Separate limits may apply to input and output.

Context windowContext limit in tokens · higher is better
Ternary Bonsai 2 27BRank 77 of 112262K
Kimi K2.6262K
Qwen 3.8 27B262K
Kimi K2.7 Code262K
Kimi K2.5262K
Kimi K2 Thinking262K
Mistral Medium 3.5262K

Can I run Ternary Bonsai 2 27B locally?

Yes, the weights are open.

Stated by PrismML

Open weights
yes
License
Apache 2.0
Parameters
27.4B
active per token
n/a

Sources and data date

Show all 13 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

No active result from the reviewed external evaluators can currently be attributed to this model. Other source evidence remains available below.

Without vendor claims and historical or disputed results; those stay labelled in the single values.

TypeEvidence and data date
Research statusResearch date October 4, 2026. 12 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Not published

category-aggregation

Note

The release page lists the component benchmarks per category but does not publish the score scale, aggregation formula, individual component scores for each category, denominators, prompting, decoding settings or evaluation date.

Unresolved

profile-specific-generalization

Note

The external report explicitly treats reasoning-off as a separate material profile and does not support transfer to reasoning-on or other quantizations. The team roster has no separate per-configuration model ID, so the exact distinction is retained in every score configuration and caveat.

Unresolved

separate prefill-curve result

Note

The report separately lists a prefill curve with pp512 293 tok/s while the llama-bench table reports 313.0 tok/s for dual T4; the curve's method/context is not sufficiently specified to merge or substitute, so it was not added.

Additional sourcePrismML Bonsai 2 27B announcement (retrieved October 3, 2026; October 17, 2026) · PrismML Bonsai 2 27B announcement · Editorial description reviewed October 4, 2026
Additional sourceTernary Bonsai 2 model card (retrieved October 3, 2026) · Ternary Bonsai 2 model card · Editorial description reviewed October 4, 2026
Additional sourcePrismML whitepaper Tables 7, 8, 10 and methodology (retrieved October 4, 2026)
Additional sourceWumboLabs, Bonsai 2 27B WELP methodology-revision supplement (retrieved October 17, 2026)
Additional sourceBonsai-demo community benchmark report (retrieved October 18, 2026)
Additional sourceBonsai-demo community issue #181 by xzphot (retrieved October 18, 2026)
Additional sourcePrismML Bonsai 2 community benchmarks, RTX 5090 Linux report (retrieved October 18, 2026)
Additional sourcePrismML Bonsai 2 community benchmarks, RTX 5080 Windows report (retrieved October 18, 2026)
Additional sourceinstax-dutta GitHub Gist (retrieved October 19, 2026)
Additional sourceTsotchke Corporation / GeoRefine, What ternary keeps, and what it loses (retrieved October 22, 2026)
Additional sourceWumboLabs WELP methodology-revision supplement, thinking-off profile (retrieved October 23, 2026)
Additional sourceModel metadata (retrieved October 17, 2026; October 23, 2026)
Additional sourceModel metadata (retrieved October 18, 2026)