
Inception LabsLanguage modelActive

Mercury 2

Mercury 2 has no overall index value yet because there are too few independent benchmark results.

Popularityno data yet

n/ano search or usage data

Summary

Mercury 2 generates answers by refining text in parallel rather than through autoregressive token-by-token decoding. Inception Labs applies a diffusion approach, more commonly associated with image generation, to a reasoning language model.

The provider specifies a 128K-token context window. It is available through the Inception API and Mercury Chat, with Mercury 2.5 later expanding context to 260K tokens.

Mercury 2 in our own test

We show the latest attempt without fixes; it does not count toward the overall index.

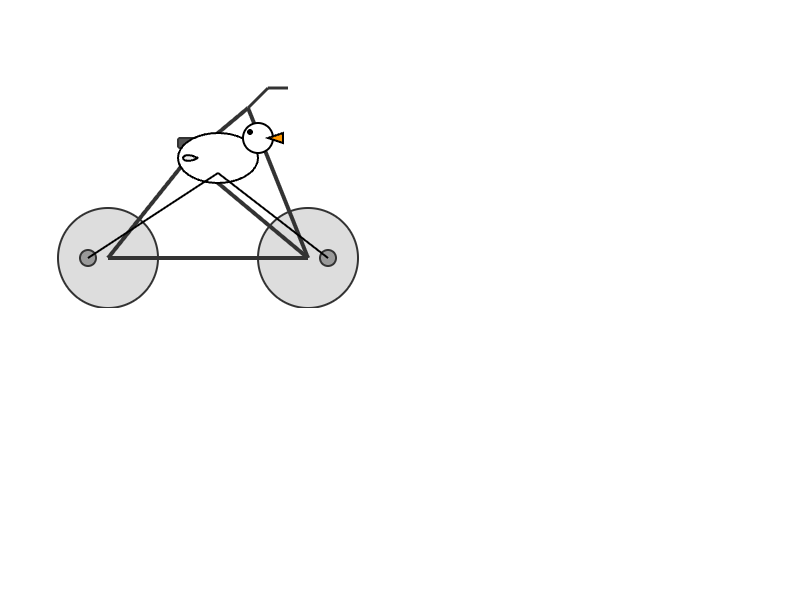
Mercury 2: Pelican on a bicycle
A community classic for free-form SVG drawing.

Pelican on a bicycle

Prompt

Generate an SVG of a pelican riding a bicycle

Oct 5, 2026 · 5.3 s · $0.0017

Test details
Run date
Oct 5, 2026
API provider
openrouter
Requested API model
inception/mercury-2
Reasoning setting
high
Token limit including reasoning
8,192 tokens
Output tokens
2,323 tokens
Cost of the attempt
$0.0017
Response time
5.3 s
API model reported in response
inception/mercury-2
Pinned endpoint
Inception | inception/mercury-2-20260304
Temperature
Provider default
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating

Visually reviewed. This individual test does not establish overall model quality.

Task origin: Simon Willison
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Mercury 2

Unavailable in this round

All benchmark results

Every published result with its source, test setup and comparison models.

Show all 32 published benchmark results

Page 1 of 3

Measurements without matching peer values

These measurements have no matching peer values under the same test conditions. Their original values and sources remain available here.

CritPt v2: Overall (Show measurement, test conditions, and source)
Source value
0.8489795918
Metric
pass@1 accuracy
Unit
%
Benchmark version
v2
Category
reasoning
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
disputed
Retrieved at
2026-11-02
Methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). AA source value for average reasoning tokens before the answer: 0. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. The full CritPt v2 run covers 70 questions with five repeats. The official grading server reports pass@1.. Source model ID: artificial-analysis/016d330a-2141-4afa-b2fc-62b314423dc1/mercury-2/mercury-2. Source model name: Mercury 2. Provider reported by source: Inception. Model snapshot: Mercury 2. Evaluator: Artificial Analysis. Dataset type: artificial-analysis-evaluation. Tool policy: Python functions, symbolic expressions, and numerical answers; official grading server. Attempts: 70 questions, five repeats per question, pass@1. Reasoning: reasoning enabled. Reasoning effort: high. Score display: 0.8%. Source ID: artificial-analysis. Evidence capture ID: aa-model-page-2026-11-02-67d46be20a5b. Source payload hash: 67d46be20a5b412db6cfb60ad190441fcaa5513500b8fd47d033168d0e97b6b2. Parser version: artificial-analysis-rsc-models-v3. Imported at: 2026-11-02. Source cohort: artificial-analysis-critpt-v2:v2:standalone:reasoning:effort=high:suffix=unspecified
Comparison methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). AA source value for average reasoning tokens before the answer: 0. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. The full CritPt v2 run covers 70 questions with five repeats. The official grading server reports pass@1.. Tool policy: Python functions, symbolic expressions, and numerical answers; official grading server. Attempts: 70 questions, five repeats per question, pass@1. Reasoning: reasoning enabled. Reasoning effort: high
Context
This AA source field contains the original CritPt score. The earlier CritPt v2 attribution was incorrect; the value and former label remain as disputed historical evidence.. The source dataset marks this result as disputed. It remains visible as documented evidence, but is not reliable comparative proof.
Source Artificial Analysis
IFBench: Overall (Show measurement, test conditions, and source)
Source value
69.7959183673
Metric
IFBench prompt-level loose accuracy (pass@1)
Unit
%
Benchmark version
AA test set: 294 questions
Category
general
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
superseded
Retrieved at
2026-11-02
Methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). AA source value for average reasoning tokens before the answer: 0. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. Artificial Analysis runs 294 questions from the IFBench test set with five repeats per question. The official evaluator scores prompt-level accuracy in loose mode as pass@1.. Source model ID: artificial-analysis/016d330a-2141-4afa-b2fc-62b314423dc1/mercury-2/mercury-2. Source model name: Mercury 2. Provider reported by source: Inception. Model snapshot: Mercury 2. Evaluator: Artificial Analysis. Dataset type: artificial-analysis-evaluation. Tool policy: Single-turn answer evaluated with the official IFBench source code. Attempts: pass@1, 5 repeats per question. Reasoning: reasoning enabled. Reasoning effort: high. Score display: 69.8%. Source ID: artificial-analysis. Evidence capture ID: aa-model-page-2026-11-02-67d46be20a5b. Source payload hash: 67d46be20a5b412db6cfb60ad190441fcaa5513500b8fd47d033168d0e97b6b2. Parser version: artificial-analysis-rsc-models-v3. Imported at: 2026-11-02. Source cohort: artificial-analysis-ifbench:AA test set: 294 questions:standalone:reasoning:effort=high:suffix=unspecified
Comparison methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). AA source value for average reasoning tokens before the answer: 0. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. Artificial Analysis runs 294 questions from the IFBench test set with five repeats per question. The official evaluator scores prompt-level accuracy in loose mode as pass@1.. Tool policy: Single-turn answer evaluated with the official IFBench source code. Attempts: pass@1, 5 repeats per question. Reasoning: reasoning enabled. Reasoning effort: high
Context
The often cited 58 refers to verifiable out-of-domain constraint types, not the number of questions in AA's test run.. This result is retained as historical evidence and is not interchangeable with current results.
Source Artificial Analysis
IFBench: Overall (Show measurement, test conditions, and source)
Source value
69.7959183673
Metric
IFBench prompt-level loose accuracy (pass@1)
Unit
%
Benchmark version
AA test set: 294 questions
Category
general
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-11-07
Methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). This source capture does not provide an average reasoning-token count. Artificial Analysis runs 294 questions from the IFBench test set with five repeats per question. The official evaluator scores prompt-level accuracy in loose mode as pass@1.. Source model ID: artificial-analysis/016d330a-2141-4afa-b2fc-62b314423dc1/mercury-2/mercury-2. Source model name: Mercury 2. Provider reported by source: Inception. Model snapshot: Mercury 2. Evaluator: Artificial Analysis. Dataset type: artificial-analysis-evaluation. Tool policy: Single-turn answer evaluated with the official IFBench source code. Attempts: pass@1, 5 repeats per question. Reasoning: reasoning enabled. Reasoning effort: high. Score display: 69.8%. Source ID: artificial-analysis. Evidence capture ID: aa-model-page-2026-11-07-b96e3ffc8c5b. Source payload hash: b96e3ffc8c5b052aa56f96d05e89d02b8cc234a75085820fca0ca2a39e498274. Parser version: artificial-analysis-rsc-models-v4. Imported at: 2026-11-07. Source cohort: artificial-analysis-ifbench:AA test set: 294 questions:standalone:reasoning:effort=high:suffix=unspecified
Comparison methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). This source capture does not provide an average reasoning-token count. Artificial Analysis runs 294 questions from the IFBench test set with five repeats per question. The official evaluator scores prompt-level accuracy in loose mode as pass@1.. Tool policy: Single-turn answer evaluated with the official IFBench source code. Attempts: pass@1, 5 repeats per question. Reasoning: reasoning enabled. Reasoning effort: high
Context
The often cited 58 refers to verifiable out-of-domain constraint types, not the number of questions in AA's test run.
Source Artificial Analysis
PinchBench · task success rate (Show measurement, test conditions, and source)
Source value
78
Metric
Task success rate
Unit
%
Direction
Higher is better
Source type
vendor-reported
Evaluator
Inception Labs, Mercury 2 on PinchBench: Fast Diffusion Models and the Personal Agent Era
Status
active
Retrieved at
2026-10-21
Methodology
Vendor-reported result. Inception Labs reports Mercury 2 evaluated on PinchBench, an OpenClaw agent benchmark covering real-world tool use, multistep reasoning, ambiguous instructions, and practical task outcomes. The report provides a success rate but no sample count, measurement date, or immutable serving revision.
Context
Vendor-reported result, not independently reproduced in the opened PinchBench page. The page's visible current top-ten table does not show Mercury 2; no per-model N or immutable serving revision is disclosed.
Source Inception Labs, Mercury 2 on PinchBench: Fast Diffusion Models and the Personal Agent Era
GDPval-AA: Overall (Show measurement, test conditions, and source)
Source value
501.73
Metric
GDPval-AA Elo
Unit
Elo
Benchmark version
v2.1
Category
agentic
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
superseded
Retrieved at
2026-11-02
Methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). AA source value for average reasoning tokens before the answer: 0. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Source model ID: artificial-analysis/016d330a-2141-4afa-b2fc-62b314423dc1/mercury-2/mercury-2. Source model name: Mercury 2. Provider reported by source: Inception. Model snapshot: Mercury 2. Evaluator: Artificial Analysis. Dataset type: artificial-analysis-evaluation. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled. Reasoning effort: high. Source ID: artificial-analysis. Evidence capture ID: aa-model-page-2026-11-02-67d46be20a5b. Source payload hash: 67d46be20a5b412db6cfb60ad190441fcaa5513500b8fd47d033168d0e97b6b2. Parser version: artificial-analysis-rsc-models-v3. Imported at: 2026-11-02. Source cohort: artificial-analysis-gdpval-aa:v2.1:standalone:reasoning:effort=high:suffix=unspecified
Comparison methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). AA source value for average reasoning tokens before the answer: 0. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled. Reasoning effort: high
Context
This result is retained as historical evidence and is not interchangeable with current results.
Source Artificial Analysis
GDPval-AA: Overall (Show measurement, test conditions, and source)
Source value
502.12
Metric
GDPval-AA Elo
Unit
Elo
Benchmark version
v2.1
Category
agentic
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
superseded
Retrieved at
2026-10-29
Methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). AA source value for average reasoning tokens before the answer: 0. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Source model ID: artificial-analysis/016d330a-2141-4afa-b2fc-62b314423dc1/mercury-2/mercury-2. Source model name: Mercury 2. Provider reported by source: Inception. Model snapshot: Mercury 2. Evaluator: Artificial Analysis. Dataset type: artificial-analysis-evaluation. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled. Reasoning effort: high. Source ID: artificial-analysis. Evidence capture ID: aa-model-page-2026-10-29-5a1b1cf41cd1. Source payload hash: 5a1b1cf41cd14d4fa7e1b5c737732505ff7f014395c8a19ff9385c13df09b106. Parser version: artificial-analysis-rsc-models-v3. Imported at: 2026-10-29. Source cohort: artificial-analysis-gdpval-aa:v2.1:standalone:reasoning:effort=high:suffix=unspecified
Comparison methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). AA source value for average reasoning tokens before the answer: 0. Its methodology averages 60 varied prompts and assumes 2,000 when no average is available. This is not a token cap. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled. Reasoning effort: high
Context
This result is retained as historical evidence and is not interchangeable with current results.
Source Artificial Analysis
GDPval-AA: Overall (Show measurement, test conditions, and source)
Source value
501.73
Metric
GDPval-AA Elo
Unit
Elo
Benchmark version
v2.1
Category
agentic
Task
overall
Task label
Overall
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-11-07
Methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). This source capture does not provide an average reasoning-token count. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Source model ID: artificial-analysis/016d330a-2141-4afa-b2fc-62b314423dc1/mercury-2/mercury-2. Source model name: Mercury 2. Provider reported by source: Inception. Model snapshot: Mercury 2. Evaluator: Artificial Analysis. Dataset type: artificial-analysis-evaluation. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled. Reasoning effort: high. Source ID: artificial-analysis. Evidence capture ID: aa-model-page-2026-11-07-b96e3ffc8c5b. Source payload hash: b96e3ffc8c5b052aa56f96d05e89d02b8cc234a75085820fca0ca2a39e498274. Parser version: artificial-analysis-rsc-models-v4. Imported at: 2026-11-07. Source cohort: artificial-analysis-gdpval-aa:v2.1:standalone:reasoning:effort=high:suffix=unspecified
Comparison methodology
Exact AA configuration: Mercury 2 (release mercury-2, row mercury-2, UUID 016d330a-2141-4afa-b2fc-62b314423dc1, reasoning=true, effort=high, suffix=not specified). This source capture does not provide an average reasoning-token count. 220 tasks with one run each. AA scores outcomes through pairwise panel comparisons and anchors the Elo scale at DeepSeek V4.1 Flash (Max) at 1,600.. Harness: Artificial Analysis Stirrup. Agent: Stirrup agent. Tool policy: Agentic task completion with file outputs. Attempts: 220 tasks, one run per task; panel pairwise judgments. Reasoning: reasoning enabled. Reasoning effort: high
Source Artificial Analysis
AA-Omniscience Index (Show measurement, test conditions, and source)
Source value
-50.7166666667
Metric
AA-Omniscience Index
Unit
points
Benchmark version
AA-Omniscience (current evaluator version not exposed on model page)
Category
source-specific
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-10-04
Methodology
Independent evaluation. Artificial Analysis exact model-page result; Omniscience index is a -100 to 100 index over the evaluator's six domains. Serving configuration: reasoning_effort=high.
Context
Source-specific observation; it is not a shared comparison cohort.
Source Artificial Analysis
AA-Omniscience Accuracy (Show measurement, test conditions, and source)
Source value
0.2118333333
Metric
AA-Omniscience Accuracy
Unit
ratio
Benchmark version
AA-Omniscience (current evaluator version not exposed on model page)
Category
source-specific
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-10-04
Methodology
Independent evaluation. Artificial Analysis exact model-page result; accuracy is the correct-answer proportion for the Omniscience evaluator. Serving configuration: reasoning_effort=high.
Context
Source-specific observation; it is not a shared comparison cohort.
Source Artificial Analysis
AA-Omniscience Hallucination Rate (Show measurement, test conditions, and source)
Source value
0.9122436033
Metric
AA-Omniscience Hallucination Rate
Unit
ratio
Benchmark version
AA-Omniscience (current evaluator version not exposed on model page)
Category
source-specific
Direction
Lower is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-10-04
Methodology
Independent evaluation. Artificial Analysis exact model-page result; hallucination rate is the evaluator's hallucinated-answer proportion. Serving configuration: reasoning_effort=high.
Context
Source-specific observation; it is not a shared comparison cohort.
Source Artificial Analysis
GDPval-AA (Show measurement, test conditions, and source)
Source value
497.66
Metric
GDPval-AA
Unit
elo
Benchmark version
GDPval-AA v2.1
Category
source-specific
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-10-04
Methodology
Independent evaluation. Artificial Analysis exact model-page result; GDPval-AA v2.1 reports Elo for the 220-task evaluator, anchored to DeepSeek V4.1 Flash (max) at 1600. Serving configuration: reasoning_effort=high.
Context
Source-specific observation; it is not a shared comparison cohort.
Source Artificial Analysis
τ²-Bench Telecom (Show measurement, test conditions, and source)
Source value
0.7076023392
Metric
τ²-Bench Telecom
Unit
ratio
Category
source-specific
Direction
Higher is better
Source type
independent-evaluator
Evaluator
Artificial Analysis
Status
active
Retrieved at
2026-10-04
Methodology
Independent evaluation. Artificial Analysis exact model-page result; the model page does not expose a version label for this τ²-Bench Telecom result. Serving configuration: reasoning_effort=high.
Context
Source-specific observation; it is not a shared comparison cohort.
Source Artificial Analysis

Page 1 of 3

All specifications

Architecture

Architecture
Diffusion-based response generation
Source: Architecture

Input and output

Context window
128K
Source: Context window
Capabilities
Tunable reasoning, native tool use, and schema-aligned JSON
Source: Capabilities

Watermarking and provenance

AI watermarking refers to invisible signals embedded in the output. Visible marks and provenance metadata are listed separately. Unknown means there is insufficient evidence for that particular field.

AI watermarking
Unknown
no source
Watermarking technique
Not known
no source

Licence and access

Availability
API and Mercury Chat
Source: Availability
Shutdown
None announced
no source

Prices

No subscription access recorded in Germany.

All plans in the AI subscription comparison

Frequently asked questions about Mercury 2

Can I run Mercury 2 locally?

No. Inception Labs does not publish the weights.

Stated by Inception Labs

Open weights
no
License
n/a
Parameters
n/a
active per token
n/a

Sources and data date

Show all 11 sources

Benchmark sources at a glance

Which independent evaluators tested this model. This is coverage, not a quality ranking.

EvaluatorTest seriesComposite indicesRecorded active measurements
Artificial Analysis15019

Without vendor claims and historical or disputed results; those stay labelled in the single values.

TypeEvidence and data date
Research statusResearch date October 4, 2026. 7 source URLs checked. This documents the inspected sources, not an exhaustive inventory of every publication.
Not published

immutable serving revision and confidence interval

Note

The article does not report an immutable revision or 95% interval.

Unresolved

WideSearch score scale and method

Note

The article does not state the 0.923 score's scale/unit, direction, sample count, or interval.

Unresolved

FRAMES latency statistic

Note

The article gives 10.8 seconds but does not say whether this is a mean, median, single observation, or another statistic; no interval is given.

Additional sourceInception Labs Mercury 2 announcement (retrieved October 3, 2026; October 4, 2026; October 19, 2026) · Inception Labs Mercury 2 announcement · Editorial description reviewed October 4, 2026
Additional sourceInception original publication dates (retrieved October 3, 2026)
Additional sourceArtificial Analysis (retrieved November 2, 2026)
Additional sourceArtificial Analysis (retrieved October 29, 2026; November 2, 2026; November 7, 2026)
Additional sourceArtificial Analysis (retrieved November 2, 2026; November 7, 2026)
Additional sourceArtificial Analysis (retrieved October 4, 2026)
Additional sourceInception Labs, Mercury 2 for Search (retrieved October 17, 2026; October 19, 2026)
Additional sourceAbhinav Raghunathan, custom Mercury 2 RAG benchmark (retrieved October 19, 2026)
Additional sourceInception Labs, Mercury 2 on PinchBench: Fast Diffusion Models and the Personal Agent Era (retrieved October 21, 2026)
Additional sourceModel metadata (retrieved October 4, 2026)12