
GPT-5.5vs.Qwen 3.8 27B

Which one is better?

GPT-5.5 is clearly ahead in the overall index, but costs 125 times (input) and 12 times (output) as much per token.

IntelligenceOverall index, 0 to 100 · higher is better
53

GPT-5.5

Rank 19 to 35

11

Qwen 3.8 27B

Rank 44 to 57

SpeedTokens per second · higher is better
89

GPT-5.5

fairly slow

40

Qwen 3.8 27B

slow

PriceDollars per 1M tokens · lower is better
$11.25

GPT-5.5

expensive

$0.66

Qwen 3.8 27B

fairly cheap

GPT-5.5

Subscription

No OpenAI subscription includes this model. Through other providers from ≈ €6.36 a month (ElevenLabs Starter, with limited credits). 41 plans in Germany.

Via API

$5 input, $30 output per 1M tokens, unchanged since our price tracking began on Aug 14, 2026.

Note
There is a successor: GPT-5.6 Sol (rank 12 to 18, $4 input, $20 output).

Qwen 3.8 27B

Subscription

No Alibaba subscription includes this model. Through other providers from ≈ €1.06 a month (Command Code Go, with limited credits). 10 plans in Germany.

Via API

$0.04 input, $2.50 output per 1M tokens according to the provider; the price index has listed it at $0.42 and $3 since Oct 27, 2026.

Overall index with data through Oct 29, 2026 · Prices from Oct 29, 2026 · Speed: measured by Artificial Analysis · Subscriptions as of Oct 24, 2026 · Subscription prices incl. VAT

Where is the difference?

Values from 0 to 100 per task area. We only name a winner when the gap is large enough and there are enough tests.

GPT-5.5 ahead: 6Qwen 3.8 27B ahead: 0level: 3too little data: 1of 10 areas

GPT-5.5Qwen 3.8 27B0 to 100, higher is better
Areas in the overall index
CodingGPT-5.5 aheadGPT-5.5: 39Qwen 3.8 27B: 13
ReasoninglevelGPT-5.5: 50Qwen 3.8 27B: 6
MathematicsGPT-5.5 aheadGPT-5.5: 59Qwen 3.8 27B: 8
KnowledgeGPT-5.5 aheadGPT-5.5: 64Qwen 3.8 27B: 5
AgentslevelGPT-5.5: 46Qwen 3.8 27B: 21
Generalonly GPT-5.5 has a scoreGPT-5.5: 50Qwen 3.8 27B: not enough data
MultimodalGPT-5.5 aheadGPT-5.5: 51Qwen 3.8 27B: 13
Specialist fields
FinancelevelGPT-5.5: 49Qwen 3.8 27B: 34
LegalGPT-5.5 aheadGPT-5.5: 57Qwen 3.8 27B: 23
HealthGPT-5.5 aheadGPT-5.5: 59Qwen 3.8 27B: 3
Show 3 more areas that do not count toward the overall index
GPT-5.5Qwen 3.8 27B0 to 100, higher is better
Cybersecurityonly Qwen 3.8 27B has a scoreGPT-5.5: not enough dataQwen 3.8 27B: 19
Searchonly GPT-5.5 has a scoreGPT-5.5: 87Qwen 3.8 27B: not enough data
Productivityonly GPT-5.5 has a scoreGPT-5.5: 35Qwen 3.8 27B: not enough data

See for yourself: same task, one attempt

The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.

Pelican on a bicycle

A community classic for free-form SVG drawing.

GPT-5.5
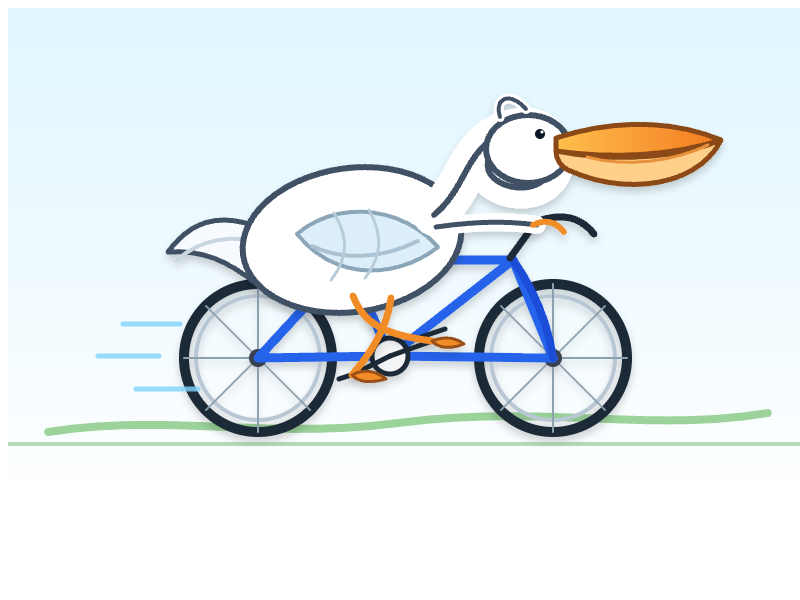
GPT-5.5: Pelican on a bicycle
A community classic for free-form SVG drawing.

Reasoning (requested): high

Current attempt
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
openai/gpt-5.5
API model reported in response
openai/gpt-5.5
Reasoning setting
high
Pinned endpoint
OpenAI | openai/gpt-5.5-20260423
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
25.9 s

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (1)
  • Sep 7, 2026API request failedReasoning setting: high

Qwen 3.8 27B

Not tested yet

Prompt and test conditions

Generate an SVG of a pelican riding a bicycle

Token limit including reasoning: 8,192 tokens

Task origin (Simon Willison)
SVG short test

SVG short test

One SVG task with the same fixed settings for every model, without hidden thinking.

Shared test round: 43b8c5c46830

GPT-5.5

Unavailable in this round

Qwen 3.8 27B
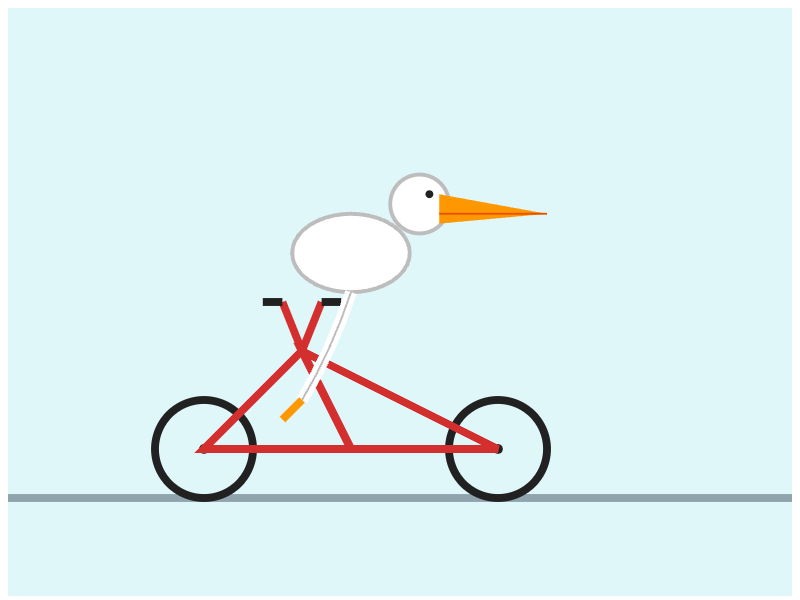
Qwen 3.8 27B: SVG short test
Test run: Oct 14, 2026 · alibaba
Test detailsAPI reports 0 reasoning tokensAPI model: qwen/qwen3.8-27b865 output tokens

All data side by side

The better value is bold. For the overall index only when the gap is clear.

MetricGPT-5.5Qwen 3.8 27B
Intelligence
Overall index0 to 100, higher is better5311
RankRank 19 to 35 of 95Rank 44 to 57 of 95
Price per 1M tokens
Inputwhat you send$5above 272,000 tokens: $10$0.04
Outputwhat the model writes$30above 272,000 tokens: $45$2.50
Speed
Tokens per second8940
Technical
Context windowhow much text the model reads at once1.05 M tokens≈ 1,580 A4 pages262,144 tokens≈ 390 A4 pages
Knowledge cutoffDec 1, 2025n/a
ReleasedApr 23, 2026Aug 14, 2026
AvailabilityActiveActive
Open weightsnoyes

Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis

Shared benchmarks

Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.

A: GPT-5.5B: Qwen 3.8 27B

Code MigrationOverall · higher is betterTest setup not documented as identicalGPT-5.5: 45.2%Qwen 3.8 27B: 14.2%Vals AIAs of 10/18/2026
CritPt v2Overall · higher is betterGPT-5.5: 27.1%Qwen 3.8 27B: 5.4%Artificial AnalysisAs of 10/29/2026
EMBOverall · higher is betterTest setup not documented as identicalGPT-5.5: 64.5%Qwen 3.8 27B: 59.7%Vals AIAs of 10/20/2026
Finance Agent (v2)Overall · higher is betterTest setup not documented as identicalGPT-5.5: 51.8%Qwen 3.8 27B: 48.6%Vals AIAs of 10/20/2026
GDPval-AAOverall · higher is betterGPT-5.5: 1,359.62 eloQwen 3.8 27B: 1,427.26 eloArtificial AnalysisAs of 10/29/2026
GPQA DiamondOverall · higher is betterTest setup not documented as identicalGPT-5.5: 93.2%Qwen 3.8 27B: 88.9%Vals AIAs of 09/01/2026
Legal Research BenchOverall · All-pass · higher is betterTest setup not documented as identicalGPT-5.5: 40.4%Qwen 3.8 27B: 36.1%Vals AIAs of 10/26/2026
LegalBenchOverall · higher is betterTest setup not documented as identicalGPT-5.5: 86.5%Qwen 3.8 27B: 82.4%Vals AIAs of 10/13/2026
LiveCodeBenchOverall · higher is betterTest setup not documented as identicalGPT-5.5: 85.3%Qwen 3.8 27B: 84%Vals AIAs of 09/01/2026
MedCodeOverall · higher is betterTest setup not documented as identicalGPT-5.5: 49.1%Qwen 3.8 27B: 28.7%Vals AIAs of 10/13/2026
Show 54 more benchmarks
MedScribeOverall · higher is betterTest setup not documented as identicalGPT-5.5: 86.9%Qwen 3.8 27B: 83.8%Vals AIAs of 10/13/2026
MMLU ProOverall · higher is betterTest setup not documented as identicalGPT-5.5: 88.1%Qwen 3.8 27B: 84.3%Vals AIAs of 09/01/2026
MMMU ProOverall · higher is betterTest setup not documented as identicalGPT-5.5: 88.3%Qwen 3.8 27B: 83.9%Vals AIAs of 09/01/2026
MMMU-ProOverall · higher is betterGPT-5.5: 79.9%Qwen 3.8 27B: 76.3%Artificial AnalysisAs of 10/29/2026
MortgageTaxOverall · higher is betterTest setup not documented as identicalGPT-5.5: 68.8%Qwen 3.8 27B: 64.9%Vals AIAs of 09/01/2026
ProgramBenchOverall · higher is betterTest setup not documented as identicalGPT-5.5: 0.5%Qwen 3.8 27B: 0%Vals AIAs of 10/20/2026
SkillsBenchOverall · higher is betterTest setup not documented as identicalGPT-5.5: 62.2%Qwen 3.8 27B: 38.1%Vals AIAs of 09/27/2026
SWE-bench VerifiedOverall · higher is betterTest setup not documented as identicalGPT-5.5: 82.6%Qwen 3.8 27B: 86%Vals AIAs of 09/01/2026
Tax Agent BenchOverall · higher is betterTest setup not documented as identicalGPT-5.5: 21.8%Qwen 3.8 27B: 30.9%Vals AIAs of 10/26/2026
TaxEval v2Overall · higher is betterTest setup not documented as identicalGPT-5.5: 75%Qwen 3.8 27B: 70.9%Vals AIAs of 09/01/2026
Terminal-Bench 2.1Overall · higher is betterTest setup not documented as identicalGPT-5.5: 76.4%Qwen 3.8 27B: 58.4%Vals AIAs of 10/01/2026
Vibe Code Bench v1.1Overall · higher is betterTest setup not documented as identicalGPT-5.5: 69.8%Qwen 3.8 27B: 64.9%Vals AIAs of 10/26/2026
Code MigrationCLI · higher is betterTest setup not documented as identicalGPT-5.5: 36.9%Qwen 3.8 27B: 2.2%Vals AIAs of 10/18/2026
CritPt v2Overall · higher is betterGPT-5.5: 18.6%Qwen 3.8 27B: 0.0%Artificial AnalysisAs of 10/29/2026
EMBComps · higher is betterTest setup not documented as identicalGPT-5.5: 64.7%Qwen 3.8 27B: 53.3%Vals AIAs of 10/20/2026
Finance Agent (v2)Adjustments · higher is betterTest setup not documented as identicalGPT-5.5: 45.7%Qwen 3.8 27B: 47.3%Vals AIAs of 10/20/2026
GDPval-AAOverall · higher is betterGPT-5.5: 1,243.45 eloQwen 3.8 27B: 1,389.29 eloArtificial AnalysisAs of 10/29/2026
GPQA DiamondFew-Shot CoT · higher is betterTest setup not documented as identicalGPT-5.5: 93.4%Qwen 3.8 27B: 88.9%Vals AIAs of 09/01/2026
Legal Research BenchAdministrative / Regulatory · All-pass · higher is betterTest setup not documented as identicalGPT-5.5: 53%Qwen 3.8 27B: 45.5%Vals AIAs of 10/26/2026
LegalBenchConclusion Tasks · higher is betterTest setup not documented as identicalGPT-5.5: 89.6%Qwen 3.8 27B: 88.4%Vals AIAs of 10/13/2026
LiveCodeBenchEasy · higher is betterTest setup not documented as identicalGPT-5.5: 98.4%Qwen 3.8 27B: 99.1%Vals AIAs of 09/01/2026
MMLU ProBiology · higher is betterTest setup not documented as identicalGPT-5.5: 94%Qwen 3.8 27B: 91.5%Vals AIAs of 09/01/2026
MMMU-ProOverall · higher is betterGPT-5.5: 81.2%Qwen 3.8 27B: 74.2%Artificial AnalysisAs of 10/29/2026
MortgageTaxNumerical Extraction · higher is betterTest setup not documented as identicalGPT-5.5: 76.2%Qwen 3.8 27B: 69.4%Vals AIAs of 09/01/2026
ProgramBenchAlmost Resolved · higher is betterTest setup not documented as identicalGPT-5.5: 9.5%Qwen 3.8 27B: 1%Vals AIAs of 10/20/2026
SkillsBenchNo Skills · higher is betterTest setup not documented as identicalGPT-5.5: 49.9%Qwen 3.8 27B: 19.1%Vals AIAs of 09/27/2026
SWE-bench Verified<15 min fix · higher is betterTest setup not documented as identicalGPT-5.5: 91.8%Qwen 3.8 27B: 90.2%Vals AIAs of 09/01/2026
Tax Agent BenchControversy & Precedence Analysis · higher is betterTest setup not documented as identicalGPT-5.5: 10%Qwen 3.8 27B: 6.7%Vals AIAs of 10/26/2026
TaxEval v2Correctness · higher is betterTest setup not documented as identicalGPT-5.5: 65.5%Qwen 3.8 27B: 60.1%Vals AIAs of 09/01/2026
Terminal-Bench 2.1Easy · higher is betterTest setup not documented as identicalGPT-5.5: 83.3%Qwen 3.8 27B: 50%Vals AIAs of 10/01/2026
Code MigrationCOBOL · higher is betterTest setup not documented as identicalGPT-5.5: 70%Qwen 3.8 27B: 50%Vals AIAs of 10/18/2026
CritPt v2Overall · higher is betterGPT-5.5: 1.4%Qwen 3.8 27B: 0.3%Artificial AnalysisAs of 10/29/2026
EMBDataroom · higher is betterTest setup not documented as identicalGPT-5.5: 81.2%Qwen 3.8 27B: 79.7%Vals AIAs of 10/20/2026
Finance Agent (v2)All-Pass · higher is betterTest setup not documented as identicalGPT-5.5: 39.6%Qwen 3.8 27B: 36.8%Vals AIAs of 10/20/2026
GDPval-AAOverall · higher is betterGPT-5.5: 978.1 eloQwen 3.8 27B: 1,082.47 eloArtificial AnalysisAs of 10/29/2026
GPQA DiamondZero-Shot CoT · higher is betterTest setup not documented as identicalGPT-5.5: 92.9%Qwen 3.8 27B: 88.9%Vals AIAs of 09/01/2026
Legal Research BenchAdministrative / Regulatory · Weighted partial credit · higher is betterTest setup not documented as identicalGPT-5.5: 86.7%Qwen 3.8 27B: 88.5%Vals AIAs of 10/26/2026
LegalBenchInterpretation Tasks · higher is betterTest setup not documented as identicalGPT-5.5: 83.8%Qwen 3.8 27B: 82%Vals AIAs of 10/13/2026
LiveCodeBenchHard · higher is betterTest setup not documented as identicalGPT-5.5: 69.7%Qwen 3.8 27B: 65.7%Vals AIAs of 09/01/2026
MMLU ProBusiness · higher is betterTest setup not documented as identicalGPT-5.5: 92%Qwen 3.8 27B: 90.2%Vals AIAs of 09/01/2026
MMMU-ProOverall · higher is betterGPT-5.5: 71.4%Qwen 3.8 27B: 69.9%Artificial AnalysisAs of 10/29/2026
MortgageTaxSemantic Extraction · higher is betterTest setup not documented as identicalGPT-5.5: 61.4%Qwen 3.8 27B: 60.5%Vals AIAs of 09/01/2026
ProgramBenchFully Resolved · higher is betterTest setup not documented as identicalGPT-5.5: 0.5%Qwen 3.8 27B: 0%Vals AIAs of 10/20/2026
SkillsBenchWith Skills · higher is betterTest setup not documented as identicalGPT-5.5: 62.2%Qwen 3.8 27B: 38.1%Vals AIAs of 09/27/2026
SWE-bench Verified>4 hours · higher is betterTest setup not documented as identicalGPT-5.5: 66.7%Qwen 3.8 27B: 66.7%Vals AIAs of 09/01/2026
Tax Agent BenchControversy & Precedence Analysis · higher is betterTest setup not documented as identicalGPT-5.5: 54.9%Qwen 3.8 27B: 48.3%Vals AIAs of 10/26/2026
TaxEval v2Stepwise Reasoning · higher is betterTest setup not documented as identicalGPT-5.5: 84.5%Qwen 3.8 27B: 81.6%Vals AIAs of 09/01/2026
Terminal-Bench 2.1Hard · higher is betterTest setup not documented as identicalGPT-5.5: 66.7%Qwen 3.8 27B: 43.3%Vals AIAs of 10/01/2026
Code MigrationCode Quality · higher is betterTest setup not documented as identicalGPT-5.5: 3.498 / 5Qwen 3.8 27B: 4.197 / 5Vals AIAs of 10/18/2026
CritPt v2Overall · higher is betterGPT-5.5: 8.0%Qwen 3.8 27B: 0.0%Artificial AnalysisAs of 10/29/2026
EMBDCF · higher is betterTest setup not documented as identicalGPT-5.5: 56.7%Qwen 3.8 27B: 50%Vals AIAs of 10/20/2026
Finance Agent (v2)Comparables · higher is betterTest setup not documented as identicalGPT-5.5: 43.7%Qwen 3.8 27B: 38.9%Vals AIAs of 10/20/2026
GDPval-AAOverall · higher is betterGPT-5.5: 1,053.48 eloQwen 3.8 27B: 1,370.88 eloArtificial AnalysisAs of 10/29/2026
Legal Research BenchBusiness & Commercial · All-pass · higher is betterTest setup not documented as identicalGPT-5.5: 37.2%Qwen 3.8 27B: 41.9%Vals AIAs of 10/26/2026

Compare another matchup