GPT-5.4 mini
Unavailable in this round
Head-to-head comparison
Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
Specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
| Attribute | GPT-5.4 mini | Gemini 4 Argon |
|---|---|---|
| Provider | OpenAI | Google DeepMind |
| Released | Mar 17, 2026 | Oct 13, 2026 |
| Availability | Active | Active |
| Model type | Proprietary | Proprietary |
| Parameters | Not published | Not published |
| Architecture | Not published | Not published |
| Context window | 400,000 tokens | 1,048,576 tokens shared across input, thinking, and output |
| Knowledge cutoff | August 31, 2025 | Not published |
| Technical sources | Model | Model |
Pricing
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
| Price type | GPT-5.4 mini | Gemini 4 Argon |
|---|---|---|
| API input | $0.75 | $2 |
| API output | $4.5 | $10 |
| Cache read | $0.075 | $0.1 |
| Cache write (5 min.) | Not listed | Not listed |
| Cache write (1 hr.) | Not listed | Not listed |
| Price verified | 09/22/2026 Source | 10/25/2026 Source |
Gemini 4 Argon, Standard pricing through November 30, 2026 Per 1 million tokens: $2.00 input, $10.00 output including thinking, and $0.10 cached input. Source | ||
Gemini 4 Argon, Standard pricing from December 1, 2026 Per 1 million tokens: $4.00 input, $20.00 output including thinking, and $0.20 cached input. Source | ||
Gemini 4 Argon, Caching Implicit caching only; explicit caching is not supported. Source | ||
Key to the marks:better valuebetter, but not conclusivetie
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
No provider tariff for Gemini 4 Argon is available in the stored OpenRouter snapshot. The official direct price is still shown.
| Model | Provider | Purchase route and tariff | Input per 1M tokens | Output per 1M tokens | Source |
|---|---|---|---|---|---|
| GPT-5.4 mini | OpenAI | Direct from developerStandard API | $0.75 | $4.5 | Source09/22/2026 |
| Azure | Via OpenRouterazure | $0.75 | $4.5 | Source10/26/2026 | |
| Azure | Via OpenRouterazure/us | $0.825 | $4.95 | Source10/26/2026 | |
| OpenAI | Via OpenRouteropenai | $0.75 | $4.5 | Source10/26/2026 | |
| OpenAI | Via OpenRouteropenai/fast | $1.5 | $9 | Source10/26/2026 | |
| OpenAI | Via OpenRouteropenai/flex | Lowest listed price: $0.375 | Lowest listed price: $2.25 | Source10/26/2026 | |
| Gemini 4 Argon | Google DeepMind | Direct from developerStandard API | Lowest listed price: $2 | Lowest listed price: $10 | Source10/25/2026 |
Benchmark index
The index combines independent benchmarks on a scale from 0 to 100. A lead only counts when a model comes first in at least 95% of 200 recalculations with randomly redrawn test families. Otherwise both count as level.
Gemini 4 Argon leads in 7 of 7 shared areas.
| Area | GPT-5.4 mini | Gemini 4 Argon |
|---|---|---|
| Coding | 5.9 | 92.4 |
| Reasoning | 8.3 | 91.6 |
| Knowledge | 2.1 | 93.6 |
| General | 4.9 | 90.2 |
| Finance | 3.6 | 94.6 |
| Legal | 1.2 | 94.9 |
| Education | 11.4 | 93.6 |
Performance
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
Not enough directly matched categories for a reliable radar
Only 0 of at least 5 categories have comparable, direct model measurements. The benchmark tables below show the available evidence without filling missing axes.
Key to the marks:better valuebetter, but not conclusivetie
| Benchmark and task | GPT-5.4 mini | Gemini 4 Argon | Source |
|---|---|---|---|
Code MigrationOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 12.936 % | Higher measured value68.173 % | Vals AISource detailsData as of: 10/12/2026 |
EMBOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 45.426 % | Higher measured value75.244 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 45.36 % | Higher measured value65.401 % | Vals AISource detailsData as of: 10/12/2026 |
Harvey's Legal Agent BenchmarkOverall · Task fully resolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 0 % | Higher measured value19.583 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchOverall · All-passTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 12.5 % | Higher measured value54.808 % | Vals AISource detailsData as of: 10/12/2026 |
ProgramBenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: fully resolved rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 0 % | Higher measured value2.5 % | Vals AISource detailsData as of: 10/12/2026 |
SAGEOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 30,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 50.813 % | Higher measured value53.645 % | Vals AISource detailsData as of: 10/08/2026 |
Tax Agent BenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 8.808 % | Higher measured value44.56 % | Vals AISource detailsData as of: 10/12/2026 |
Terminal-Bench 4.0OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 2.525 % | Higher measured value57.576 % | Vals AISource detailsData as of: 10/13/2026 |
Vals IndexOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: weighted index scoreScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 33.169 % | Higher measured value68.896 % | Vals AISource detailsData as of: 10/13/2026 |
Vibe Code Bench v1.1OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Harness: OpenHands, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Harness: OpenHands, Temperature: 1, Output limit: 262,144 tokens | 47.969 % | Higher measured value91.906 % | Vals AISource detailsData as of: 10/12/2026 |
Code MigrationCLITest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 8.2 % | Higher measured value67.564 % | Vals AISource detailsData as of: 10/12/2026 |
EMBCompsTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 40.488 % | Higher measured value82.979 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)AdjustmentsTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 45.366 % | Higher measured value60.527 % | Vals AISource detailsData as of: 10/12/2026 |
Harvey's Legal Agent BenchmarkAntitrust Competition · Criteria passedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: criteria pass rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 52.536 % | Higher measured value94.203 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchAdministrative / Regulatory · All-passTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 15.152 % | Higher measured value68.182 % | Vals AISource detailsData as of: 10/12/2026 |
ProgramBenchAlmost ResolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: almost-resolved rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 3 % | Higher measured value41 % | Vals AISource detailsData as of: 10/12/2026 |
SAGEAutomataTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 30,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 41.27 % | Higher measured value45.635 % | Vals AISource detailsData as of: 10/08/2026 |
Tax Agent BenchControversy & Precedence AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 3.333 % | Higher measured value20 % | Vals AISource detailsData as of: 10/12/2026 |
Terminal-Bench 4.0HardwareTest detailsTest setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 0 % | Higher measured value46.667 % | Vals AISource detailsData as of: 10/13/2026 |
Vals IndexCode MigrationTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 13.015 % | Higher measured value69.503 % | Vals AISource detailsData as of: 10/13/2026 |
Code MigrationCOBOLTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 27.143 % | Higher measured value70 % | Vals AISource detailsData as of: 10/12/2026 |
EMBDataroomTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 48.286 % | Higher measured value85.109 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)All-PassTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 32.369 % | Higher measured value55.789 % | Vals AISource detailsData as of: 10/12/2026 |
Harvey's Legal Agent BenchmarkAntitrust Competition · Task fully resolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 0 % | Higher measured value20 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchAdministrative / Regulatory · Weighted partial creditTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: weighted partial-credit scoreScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 69.72 % | Higher measured value92.945 % | Vals AISource detailsData as of: 10/12/2026 |
ProgramBenchFully ResolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: fully resolved rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 0 % | Higher measured value2.5 % | Vals AISource detailsData as of: 10/12/2026 |
SAGECalculusTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 30,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 59.259 % | Higher measured value84.877 % | Vals AISource detailsData as of: 10/08/2026 |
Tax Agent BenchControversy & Precedence AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 32.174 % | Higher measured value63.603 % | Vals AISource detailsData as of: 10/12/2026 |
Terminal-Bench 4.0MediaTest detailsTest setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 0 % | Higher measured value83.333 % | Vals AISource detailsData as of: 10/13/2026 |
Vals IndexEMBTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 45.426 % | Higher measured value75.244 % | Vals AISource detailsData as of: 10/13/2026 |
Code MigrationCode QualityTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: mean reviewer code-quality ratingScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 3.053 / 5 | Higher measured value3.574 / 5 | Vals AISource detailsData as of: 10/12/2026 |
EMBDCFTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 40.605 % | Higher measured value65.719 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)ComparablesTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 40.273 % | Higher measured value50.956 % | Vals AISource detailsData as of: 10/12/2026 |
Harvey's Legal Agent BenchmarkArbitration International Dispute Resolution · Criteria passedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: criteria pass rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 63.125 % | Higher measured value94.265 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchBusiness & Commercial · All-passTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 11.628 % | Higher measured value46.512 % | Vals AISource detailsData as of: 10/12/2026 |
ProgramBenchRaw Pass RateTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: raw test pass rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 54.375 % | Higher measured value83.715 % | Vals AISource detailsData as of: 10/12/2026 |
SAGELinear AlgebraTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 30,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 71.486 % | Higher measured value74.031 % | Vals AISource detailsData as of: 10/08/2026 |
Tax Agent BenchCurrent & Temporal AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 10 % | Higher measured value66.667 % | Vals AISource detailsData as of: 10/12/2026 |
Terminal-Bench 4.0MLTest detailsTest setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 0 % | Higher measured value69.697 % | Vals AISource detailsData as of: 10/13/2026 |
Vals IndexFinance Agent v2Test detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 45.36 % | Higher measured value65.401 % | Vals AISource detailsData as of: 10/13/2026 |
EMBLBOTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 41.608 % | Higher measured value68.543 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)Disclosure AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 48.338 % | Higher measured value74.496 % | Vals AISource detailsData as of: 10/12/2026 |
Harvey's Legal Agent BenchmarkArbitration International Dispute Resolution · Task fully resolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | No direct winner0 % | No direct winner0 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchBusiness & Commercial · Weighted partial creditTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: weighted partial-credit scoreScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 71.172 % | Higher measured value91.87 % | Vals AISource detailsData as of: 10/12/2026 |
SAGEPartial Differential EquationsTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 30,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 39.683 % | Higher measured value41.27 % | Vals AISource detailsData as of: 10/08/2026 |
Tax Agent BenchCurrent & Temporal AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 38.553 % | Higher measured value84.637 % | Vals AISource detailsData as of: 10/12/2026 |
Terminal-Bench 4.0OperationsTest detailsTest setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 0 % | Higher measured value55.556 % | Vals AISource detailsData as of: 10/13/2026 |
Vals IndexHLABTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 0 % | Higher measured value19.583 % | Vals AISource detailsData as of: 10/13/2026 |
EMBM&ATest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 49.814 % | Higher measured value80.97 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)Earnings AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 65.294 % | Higher measured value84.807 % | Vals AISource detailsData as of: 10/12/2026 |
Harvey's Legal Agent BenchmarkBanking Finance · Criteria passedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: criteria pass rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 68.401 % | Higher measured value95.911 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchCivil Litigation · All-passTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 14.815 % | Higher measured value51.852 % | Vals AISource detailsData as of: 10/12/2026 |
Tax Agent BenchFact-Pattern AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 6.977 % | Higher measured value39.535 % | Vals AISource detailsData as of: 10/12/2026 |
Terminal-Bench 4.0ScienceTest detailsTest setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 2.381 % | Higher measured value52.381 % | Vals AISource detailsData as of: 10/13/2026 |
Vals IndexLegal ResearchTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 12.5 % | Higher measured value54.808 % | Vals AISource detailsData as of: 10/13/2026 |
EMBMiscTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 46.346 % | Higher measured value73.951 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)Financial ModelingTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 19.617 % | Higher measured value29.803 % | Vals AISource detailsData as of: 10/12/2026 |
Harvey's Legal Agent BenchmarkBanking Finance · Task fully resolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | No direct winner0 % | No direct winner0 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchCivil Litigation · Weighted partial creditTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: weighted partial-credit scoreScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 67.267 % | Higher measured value95.082 % | Vals AISource detailsData as of: 10/12/2026 |
Tax Agent BenchFact-Pattern AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 36.518 % | Higher measured value76.678 % | Vals AISource detailsData as of: 10/12/2026 |
Terminal-Bench 4.0SecurityTest detailsTest setup not documented as identicalNo direct winnerVersion: 4.0Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 0 % | Higher measured value73.333 % | Vals AISource detailsData as of: 10/13/2026 |
Vals IndexTax AgentTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: benchmark scoreScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 36.586 % | Higher measured value76.231 % | Vals AISource detailsData as of: 10/13/2026 |
EMBOperatingTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4 mini: Snapshot: gpt-5.4-mini-2026-03-17, Reasoning: xhigh, Output limit: 128,000 tokens Gemini 4 Argon: Reasoning: high, Temperature: 1, Output limit: 262,144 tokens | 50.834 % | Higher measured value69.433 % | Vals AISource detailsData as of: 10/12/2026 |
Key to the marks:better valuebetter, but not conclusivetie | |||
Our model tests
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Shared test round: 43b8c5c46830
Unavailable in this round
Unavailable in this round
A community classic for free-form SVG drawing.
GPT-5.4 mini
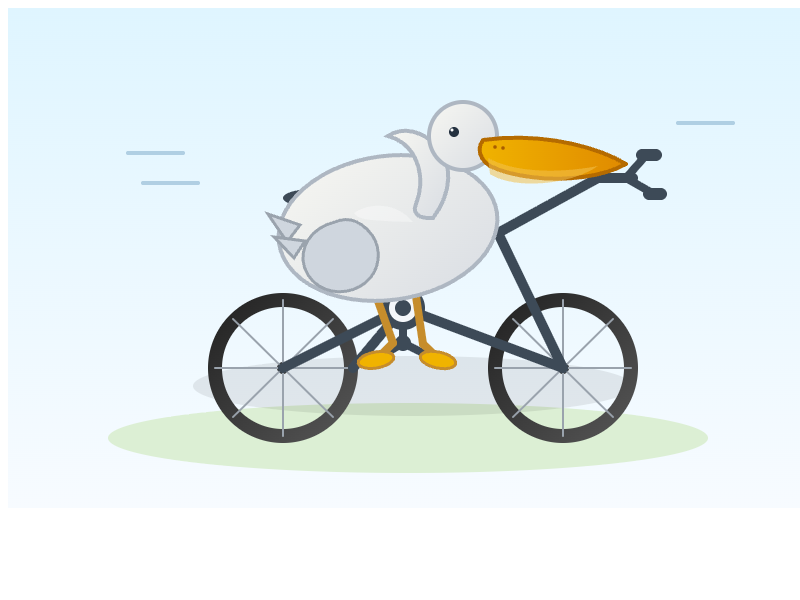
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Gemini 4 Argon
Not tested yet
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)How to read this comparison
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Compare GPT-5.4 mini and Gemini 4 Argon with other leading models using the same data and benchmark logic.