Claude Sonnet 4.6
Head-to-head comparison
Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
Specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
| Attribute | Claude Sonnet 4.6 | GPT-5.6 Luna |
|---|---|---|
| Provider | Anthropic | OpenAI |
| Released | Feb 2026 | Jul 9, 2026 |
| Availability | Active | Active |
| Model type | Proprietary | Proprietary |
| Parameters | Not published | Not published |
| Architecture | Not published | Not published |
| Context window | 1,000,000 tokens | 1,050,000 tokens |
| Knowledge cutoff | August 2025 | February 16, 2026 |
| Technical sources | Model, Context | Model, Context, Knowledge cutoff |
Pricing
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
| Price type | Claude Sonnet 4.6 | GPT-5.6 Luna |
|---|---|---|
| API input | $3 | $0.2 ≤272K / $0.4 >272K |
| API output | $15 | $1.2 ≤272K / $1.8 >272K |
| Cache read | $0.3 | $0.02 ≤272K / $0.04 >272K |
| Cache write (5 min.) | $3.75 | $0.25 ≤272K / $0.5 >272K |
| Cache write (1 hr.) | $6 | Not listed |
| Price verified | 09/22/2026 Source | 09/22/2026 Source |
Key to the marks:better valuebetter, but not conclusivetie
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
| Model | Provider | Purchase route and tariff | Input per 1M tokens | Output per 1M tokens | Source |
|---|---|---|---|---|---|
| Claude Sonnet 4.6 | Anthropic | Direct from developerStandard API | Lowest listed price: $3 | Lowest listed price: $15 | Source09/22/2026 |
| Amazon Bedrock | Via OpenRouteramazon-bedrock/eu-west-1 | $3.3 | $16.5 | Source10/26/2026 | |
| Amazon Bedrock | Via OpenRouteramazon-bedrock/global | Lowest listed price: $3 | Lowest listed price: $15 | Source10/26/2026 | |
| Amazon Bedrock | Via OpenRouteramazon-bedrock/us | $3.3 | $16.5 | Source10/26/2026 | |
| Anthropic | Via OpenRouteranthropic | Lowest listed price: $3 | Lowest listed price: $15 | Source10/26/2026 | |
| Azure | Via OpenRouterazure/global | Lowest listed price: $3 | Lowest listed price: $15 | Source10/26/2026 | |
| Claude Platform on AWS | Via OpenRouterclaude-on-aws | Lowest listed price: $3 | Lowest listed price: $15 | Source10/26/2026 | |
| Via OpenRoutergoogle-vertex/europe | $3.3 | $16.5 | Source10/26/2026 | ||
| Via OpenRoutergoogle-vertex/global | Lowest listed price: $3 | Lowest listed price: $15 | Source10/26/2026 | ||
| Via OpenRoutergoogle-vertex/us-east5 | $3.3 | $16.5 | Source10/26/2026 | ||
| GPT-5.6 Luna | OpenAI | Direct from developerUp to 272,000 context tokens | $0.2 | $1.2 | Source09/22/2026 |
| OpenAI | Direct from developerAbove 272,000 context tokens | $0.4 | $1.8 | Source09/22/2026 | |
| Amazon Bedrock | Via OpenRouteramazon-bedrock/us-east-1 | $0.22 | $1.32 | Source10/26/2026 | |
| Azure | Via OpenRouterazure | $0.2 | $1.2 | Source10/26/2026 | |
| Azure | Via OpenRouterazure/eu | $0.22 | $1.32 | Source10/26/2026 | |
| Azure | Via OpenRouterazure/us | $0.22 | $1.32 | Source10/26/2026 | |
| OpenAI | Via OpenRouteropenai | $0.2 | $1.2 | Source10/26/2026 | |
| OpenAI | Via OpenRouteropenai/fast | $0.4 | $2.4 | Source10/26/2026 | |
| OpenAI | Via OpenRouteropenai/flex | Lowest listed price: $0.1 | Lowest listed price: $0.6 | Source10/26/2026 |
Benchmark index
The index combines independent benchmarks on a scale from 0 to 100. A lead only counts when a model comes first in at least 95% of 200 recalculations with randomly redrawn test families. Otherwise both count as level.
GPT-5.6 Luna leads in 5 of 10 shared areas. 5 areas are tied.
| Area | Claude Sonnet 4.6 | GPT-5.6 Luna |
|---|---|---|
| Coding | 17.5 | 43.1 |
| Reasoning | 22.8 | 51.1 |
| Knowledgetied | 25.0 | 15.3 |
| Agents | 14.3 | 47.6 |
| Financetied | 44.6 | 52.8 |
| Legaltied | 28.0 | 29.8 |
| Health | 13.7 | 34.5 |
| Multimodal | 20.4 | 28.3 |
| Productivitytied | 29.8 | 35.7 |
| Educationtied | 27.4 | 37.4 |
Performance
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
15 matched rows from 13 benchmark families were considered. The radar shows 6 of 6 comparable categories.
Key to the marks:better valuebetter, but not conclusivetie
| Benchmark and task | Claude Sonnet 4.6 | GPT-5.6 Luna | Source |
|---|---|---|---|
AA-BriefcaseOverallTest detailsNo documented difference in the test setupVersion: v1.1Metric: AA-Briefcase EloScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: MaxClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. | 1,062.96 elo | Winner1,342.18 elo | Artificial AnalysisSource detailsData as of: 10/19/2026 |
AA-LCROverallTest detailsNo documented difference in the test setupVersion: v1.1Metric: Pass rateScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: MaxClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. | 80.0% | Winner83.7% | Artificial AnalysisSource detailsData as of: 10/19/2026 |
AA-OmniscienceOverallTest detailsNo documented difference in the test setupVersion: unspecifiedMetric: AA-Omniscience IndexScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: MaxClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. | Winner12.217 points The index can be negative and ranges from -100 to 100 according to Artificial Analysis. | -10.283 points The index can be negative and ranges from -100 to 100 according to Artificial Analysis. | Artificial AnalysisSource detailsData as of: 10/19/2026 |
AA-Omniscience AccuracyOverallTest detailsNo documented difference in the test setupVersion: AA Omniscience diagnosticMetric: AA-Omniscience AccuracyScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max, Attempts: AA-reported aggregate; diagnostic-specific run count is not stated on the leaderboard GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: Max, Attempts: AA-reported aggregate; diagnostic-specific run count is not stated on the leaderboardClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. Proportion of all questions answered correctly, regardless of whether the model answers or abstains on other questions.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. Proportion of all questions answered correctly, regardless of whether the model answers or abstains on other questions. | 40.9% This is the separately published accuracy diagnostic, not the AA-Omniscience Index. AA identifies higher values as better. | Winner42.7% This is the separately published accuracy diagnostic, not the AA-Omniscience Index. AA identifies higher values as better. | Artificial AnalysisSource detailsData as of: 10/19/2026 |
AA-Omniscience Hallucination RateOverallTest detailsNo documented difference in the test setupVersion: AA Omniscience diagnosticMetric: AA-Omniscience Hallucination RateScoring: Lower is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max, Attempts: AA-reported aggregate; diagnostic-specific run count is not stated on the leaderboard GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: Max, Attempts: AA-reported aggregate; diagnostic-specific run count is not stated on the leaderboardClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. Proportion of incorrect answers among all non-correct responses: incorrect / (incorrect + partial answers + not attempted).GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. Proportion of incorrect answers among all non-correct responses: incorrect / (incorrect + partial answers + not attempted). | Winner48.4% This is the separately published hallucination-rate diagnostic, not the AA-Omniscience Index. AA identifies lower values as better. | 92.6% This is the separately published hallucination-rate diagnostic, not the AA-Omniscience Index. AA identifies lower values as better. | Artificial AnalysisSource detailsData as of: 10/19/2026 |
APEX-Agents-AAOverallTest detailsNo documented difference in the test setupVersion: AA public cohort: 452 tasksMetric: Pass@1 success rateScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max, Agent: Stirrup agent, Harness: Artificial Analysis Stirrup, Attempts: pass@1, averaged over 3 repeats per task GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: Max, Agent: Stirrup agent, Harness: Artificial Analysis Stirrup, Attempts: pass@1, averaged over 3 repeats per taskClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. 452 tasks from the public 480-task release, with three repeats per task. A run passes only if every rubric criterion is satisfied; the leaderboard averages pass@1 across repeats.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. 452 tasks from the public 480-task release, with three repeats per task. A run passes only if every rubric criterion is satisfied; the leaderboard averages pass@1 across repeats. | 28.0% Two Investment Banking worlds are excluded because they depend on external runtime APIs. | Winner35.8% Two Investment Banking worlds are excluded because they depend on external runtime APIs. | Artificial AnalysisSource detailsData as of: 10/19/2026 |
Artificial Analysis Intelligence IndexOverallTest detailsNo documented difference in the test setupVersion: v4.3.2Metric: Artificial Analysis Intelligence IndexScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: MaxClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. | 30.058 points | Winner37.324 points | Artificial AnalysisSource detailsData as of: 10/19/2026 |
AutomationBench-AAOverallTest detailsNo documented difference in the test setupVersion: unspecifiedMetric: Objectives completed without guardrail violationsScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: MaxClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. | 20.1% | Winner50.2% | Artificial AnalysisSource detailsData as of: 10/19/2026 |
Code MigrationOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 39.892 % | Higher measured value44.55 % | Vals AISource detailsData as of: 10/12/2026 |
CorpFin v2OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value65.307 % | 64.219 % | Vals AISource detailsData as of: 08/12/2026 |
EMBOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 60.154 % | Higher measured value67.116 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 51.035 % | Higher measured value55.044 % | Vals AISource detailsData as of: 10/12/2026 |
GDP.pdfOverallTest detailsNo documented difference in the test setupVersion: unspecifiedMetric: All-pass rateScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: MaxClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. | 15.8% | Winner24.0% | Artificial AnalysisSource detailsData as of: 10/19/2026 |
GDPval-AAOverallTest detailsNo documented difference in the test setupVersion: v2.1Metric: GDPval-AA EloScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: MaxClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. | 1,232 elo | Winner1,459.2 elo | Artificial AnalysisSource detailsData as of: 10/19/2026 |
GPQA DiamondOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 85.606 % | Higher measured value91.666 % | Vals AISource detailsData as of: 09/01/2026 |
Harvey's Legal Agent BenchmarkOverall · Task fully resolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value5 % | 1.25 % | Vals AISource detailsData as of: 10/12/2026 |
Humanity's Last ExamOverallTest detailsNo documented difference in the test setupVersion: unspecifiedMetric: Text-only pass@1 accuracyScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: MaxClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. | 33.6% Artificial Analysis describes this comparable run as 2,158 text-only questions, not the full 2,500-question dataset. | Winner39.5% Artificial Analysis describes this comparable run as 2,158 text-only questions, not the full 2,500-question dataset. | Artificial AnalysisSource detailsData as of: 10/19/2026 |
ITBench-AA (SRE)OverallTest detailsNo documented difference in the test setupVersion: AA cohort: 59 tasksMetric: Average precision at full recallScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max, Agent: Stirrup agent, Harness: Artificial Analysis Stirrup, Attempts: Average precision at full recall, 3 repeats per task GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: Max, Agent: Stirrup agent, Harness: Artificial Analysis Stirrup, Attempts: Average precision at full recall, 3 repeats per taskClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. 59 Kubernetes incident tasks, 40 public and 19 private, with three repeats per task. A run scores zero if it misses any true root cause; otherwise it receives its precision at full recall. This is the SRE slice of ITBench.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. 59 Kubernetes incident tasks, 40 public and 19 private, with three repeats per task. A run scores zero if it misses any true root cause; otherwise it receives its precision at full recall. This is the SRE slice of ITBench. | 39.8% This AA implementation covers Site Reliability Engineering only, not ITBench's other CISO and FinOps domains. | Winner40.3% This AA implementation covers Site Reliability Engineering only, not ITBench's other CISO and FinOps domains. | Artificial AnalysisSource detailsData as of: 10/19/2026 |
Legal Research BenchOverall · All-passTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value38.462 % | 36.538 % | Vals AISource detailsData as of: 10/12/2026 |
LegalBenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 82.12 % | Higher measured value84.034 % | Vals AISource detailsData as of: 10/13/2026 |
MMLU-ProOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value87.341 % | 86.036 % | Vals AISource detailsData as of: 09/01/2026 |
MMMU-ProOverallTest detailsNo documented difference in the test setupVersion: AA cohort: 1,730 questionsMetric: pass@1 accuracyScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max, Attempts: pass@1, one run per question GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: Max, Attempts: pass@1, one run per questionClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. The AA run covers 1,730 questions with ten answer options. Answers are extracted by regex and scored pass@1.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. The AA run covers 1,730 questions with ten answer options. Answers are extracted by regex and scored pass@1. | 73.3% The benchmark page describes 3,460 questions in the full MMMU-Pro dataset; AA's methodology specifies a 1,730-question run. | Winner78.6% The benchmark page describes 3,460 questions in the full MMMU-Pro dataset; AA's methodology specifies a 1,730-question run. | Artificial AnalysisSource detailsData as of: 10/19/2026 |
MMMU-ProOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 83.584 % | Higher measured value85.029 % | Vals AISource detailsData as of: 09/01/2026 |
MortgageTaxOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value67.726 % | 67.29 % | Vals AISource detailsData as of: 09/01/2026 |
ProgramBenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: fully resolved rateScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value0.5 % | 0 % | Vals AISource detailsData as of: 10/12/2026 |
Public Benefits Bench v1.1OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value62.449 % | 61.164 % | Vals AISource detailsData as of: 10/12/2026 |
SAGEOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 30,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 30,000 tokens | Higher measured value46.582 % | 44.22 % | Vals AISource detailsData as of: 10/08/2026 |
SkillsBenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Harness: OpenHands, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: OpenHands, Output limit: 128,000 tokens | 49.052 % | Higher measured value60.447 % | Vals AISource detailsData as of: 09/27/2026 |
SWE-bench VerifiedOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 77.4 % | Higher measured value93 % | Vals AISource detailsData as of: 09/01/2026 |
Tax Agent BenchOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value25.84 % | 24.815 % | Vals AISource detailsData as of: 10/12/2026 |
TaxEval v2OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value77.106 % | 76.166 % | Vals AISource detailsData as of: 09/01/2026 |
Terminal-BenchOverallTest detailsNo documented difference in the test setupVersion: 4.0Metric: Task successScoring: Higher is betterClaude Sonnet 4.6: Snapshot: Claude Sonnet 4.6 (Max), Reasoning: Max GPT-5.6 Luna: Snapshot: GPT-5.6 Luna (Max), Reasoning: MaxClaude Sonnet 4.6: Exact AA configuration: Claude Sonnet 4.6 (Max) (release claude-sonnet-4-6, row claude-sonnet-4-6-adaptive, UUID df8d14e0-3997-4e4d-b4ad-9c047acc9c69, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption.GPT-5.6 Luna: Exact AA configuration: GPT-5.6 Luna (Max) (release gpt-5-6-luna, row gpt-5-6-luna, UUID 426d24c8-49ae-482a-b4a8-20f1c53f21c1, reasoning=true, source reasoning-token configuration budget=0, suffix=Max). This configured value is not measured token consumption. | 3.0% | Winner11.6% | Artificial AnalysisSource detailsData as of: 10/19/2026 |
Terminal-Bench 2.1OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 57.303 % | Higher measured value79.026 % | Vals AISource detailsData as of: 09/28/2026 |
Vals Multimodal IndexOverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.2Metric: weighted index scoreScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 60.571 % | Higher measured value69.058 % | Vals AISource detailsData as of: 08/11/2026 |
Vibe Code Bench v1.1OverallTest detailsTest setup not documented as identicalNo direct winnerVersion: 1.1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Harness: OpenHands, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: OpenHands, Output limit: 128,000 tokens | 51.476 % | Higher measured value77.055 % | Vals AISource detailsData as of: 10/12/2026 |
Code MigrationCLITest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 30.333 % | Higher measured value36.067 % | Vals AISource detailsData as of: 10/12/2026 |
CorpFin v2Exact PagesTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 63.17 % | Higher measured value63.52 % | Vals AISource detailsData as of: 08/12/2026 |
EMBCompsTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value61.52 % | 54.573 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)AdjustmentsTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 48.92 % | Higher measured value52.027 % | Vals AISource detailsData as of: 10/12/2026 |
GPQA DiamondFew-Shot CoTTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 85.859 % | Higher measured value92.424 % | Vals AISource detailsData as of: 09/01/2026 |
Harvey's Legal Agent BenchmarkAntitrust Competition · Criteria passedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: criteria pass rateScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value87.319 % | 85.145 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchAdministrative / Regulatory · All-passTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: all-pass rateScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 43.939 % | Higher measured value48.485 % | Vals AISource detailsData as of: 10/12/2026 |
LegalBenchConclusion TasksTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 87.991 % | Higher measured value88.864 % | Vals AISource detailsData as of: 10/13/2026 |
MMLU-ProBiologyTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 92.748 % | Higher measured value93.305 % | Vals AISource detailsData as of: 09/01/2026 |
MortgageTaxNumerical ExtractionTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 74.96 % | Higher measured value75.596 % | Vals AISource detailsData as of: 09/01/2026 |
ProgramBenchAlmost ResolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: almost-resolved rateScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 2 % | Higher measured value9 % | Vals AISource detailsData as of: 10/12/2026 |
SAGEAutomataTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 30,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 30,000 tokens | Higher measured value35.318 % | 31.35 % | Vals AISource detailsData as of: 10/08/2026 |
SkillsBenchNo SkillsTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Harness: OpenHands, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Harness: OpenHands, Output limit: 128,000 tokens | 27.827 % | Higher measured value45.189 % | Vals AISource detailsData as of: 09/27/2026 |
SWE-bench Verified<15 min fixTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 87.113 % | Higher measured value96.392 % | Vals AISource detailsData as of: 09/01/2026 |
Tax Agent BenchControversy & Precedence AnalysisTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | No direct winner10 % | No direct winner10 % | Vals AISource detailsData as of: 10/12/2026 |
TaxEval v2CorrectnessTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 65.822 % | Higher measured value66.558 % | Vals AISource detailsData as of: 09/01/2026 |
Terminal-Bench 2.1EasyTest detailsTest setup not documented as identicalNo direct winnerVersion: 2.1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value100 % | 83.333 % | Vals AISource detailsData as of: 09/28/2026 |
Vals Multimodal IndexCorpFin v2Test detailsTest setup not documented as identicalNo direct winnerVersion: 1.2Metric: benchmark scoreScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value66.667 % | 65.035 % | Vals AISource detailsData as of: 08/11/2026 |
Code MigrationCOBOLTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 68.571 % | Higher measured value70 % | Vals AISource detailsData as of: 10/12/2026 |
CorpFin v2Max Fitting ContextTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value66.084 % | 64.103 % | Vals AISource detailsData as of: 08/12/2026 |
EMBDataroomTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 78.493 % | Higher measured value83.009 % | Vals AISource detailsData as of: 10/12/2026 |
Finance Agent (v2)All-PassTest detailsTest setup not documented as identicalNo direct winnerVersion: 2Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 38.795 % | Higher measured value43.285 % | Vals AISource detailsData as of: 10/12/2026 |
GPQA DiamondZero-Shot CoTTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 85.354 % | Higher measured value90.909 % | Vals AISource detailsData as of: 09/01/2026 |
Harvey's Legal Agent BenchmarkAntitrust Competition · Task fully resolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: task resolution rateScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | No direct winner0 % | No direct winner0 % | Vals AISource detailsData as of: 10/12/2026 |
Legal Research BenchAdministrative / Regulatory · Weighted partial creditTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: weighted partial-credit scoreScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | 86.797 % | Higher measured value87.513 % | Vals AISource detailsData as of: 10/12/2026 |
LegalBenchInterpretation TasksTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value82.469 % | 82.142 % | Vals AISource detailsData as of: 10/13/2026 |
MMLU-ProBusinessTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value91.888 % | 91.001 % | Vals AISource detailsData as of: 09/01/2026 |
MortgageTaxSemantic ExtractionTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value60.493 % | 58.983 % | Vals AISource detailsData as of: 09/01/2026 |
ProgramBenchFully ResolvedTest detailsTest setup not documented as identicalNo direct winnerVersion: 1Metric: fully resolved rateScoring: Higher is betterClaude Sonnet 4.6: Compute: max, Temperature: 1, Output limit: 128,000 tokens GPT-5.6 Luna: Reasoning: max, Output limit: 128,000 tokens | Higher measured value0.5 % | 0 % | Vals AISource detailsData as of: 10/12/2026 |
Key to the marks:better valuebetter, but not conclusivetie | |||
Our model tests
One SVG prompt and fixed output settings. Captures are shown only with 0 reported reasoning tokens or documented lack of reasoning controls. Identical test conditions do not make the models' internal compute identical.
Shared test round: 43b8c5c46830
Unavailable in this round
A community classic for free-form SVG drawing.
Claude Sonnet 4.6
The response reached the token limit. No complete recording is available.
Reasoning (requested): high
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
GPT-5.6 Luna
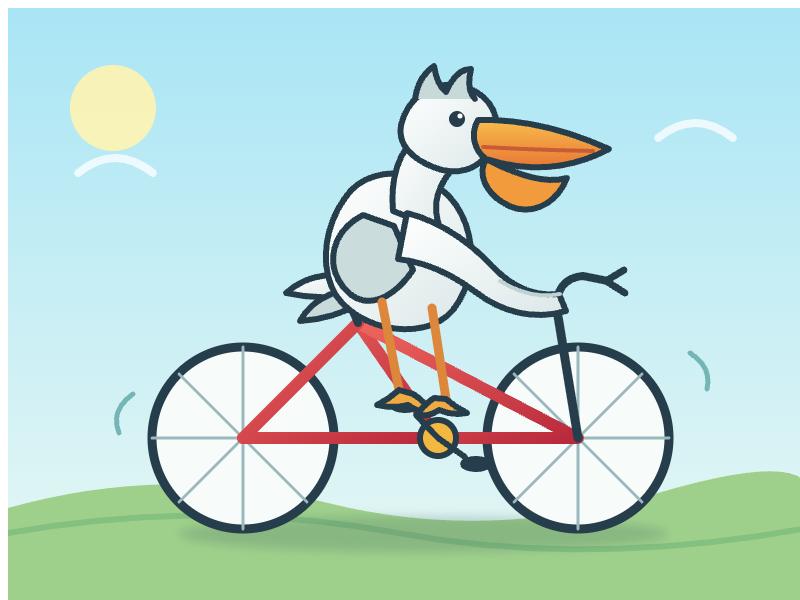
Reasoning (requested): high
Visually reviewed. This individual test does not establish overall model quality.
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)How to read this comparison
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Compare Claude Sonnet 4.6 and GPT-5.6 Luna with other leading models using the same data and benchmark logic.