AnthropicOpenAILLM matchup
Claude Opus 4.8vs.GPT-6.2 Sol
Which one is better?
GPT-6.2 Sol performs better than Claude Opus 4.8 and is cheaper: Claude Opus 4.8 costs 2.5 times as much.
Claude Opus 4.8
Rank 36
GPT-6.2 Sol
Rank 10
Claude Opus 4.8
GPT-6.2 Sol
Claude Opus 4.8
GPT-6.2 Sol
With more than 272,000 input tokens, GPT-6.2 Sol costs more: $4 input and $15 output per 1M tokens.
No clear advantage for Claude Opus 4.8.
Choose GPT-6.2 Sol for
Where is the difference?
Strengths at a glance
Opus 4.8GPT-6.2 SolMedian of all ranked models
95 % range: Opus 4.8 97.9 to 105.2, GPT-6.2 Sol 117.0 to 130.1.
The same values and verdicts as the bars below. In the close-up the net starts at 80 points, just below the weaker model's lowest value; the reference group average is 100. Not in the net because a model has no own value there or the data are too thin: Mathematics, Knowledge, General, Multimodal, Health.
GPT-6.2 Sol is ahead in 3 of 10 areas, Opus 4.8 in none.
too little data: 5GPT-6.2 Sol slightly ahead: 2GPT-6.2 Sol ahead: 3
Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.
Show 2 more areas that do not count toward the overall index
Bar length shows the gap in index points (full width 15 points, one standard deviation of the reference group). Solid means clearly ahead, hatched not certain yet, a thin grey bar level.
Which model for which task?
Everyday tasks, translated from the area values above. Each row names the values it rests on.
Claude Opus 4.8 vs. GPT-6.2 Sol in our own test
The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.
Claude Opus 4.8
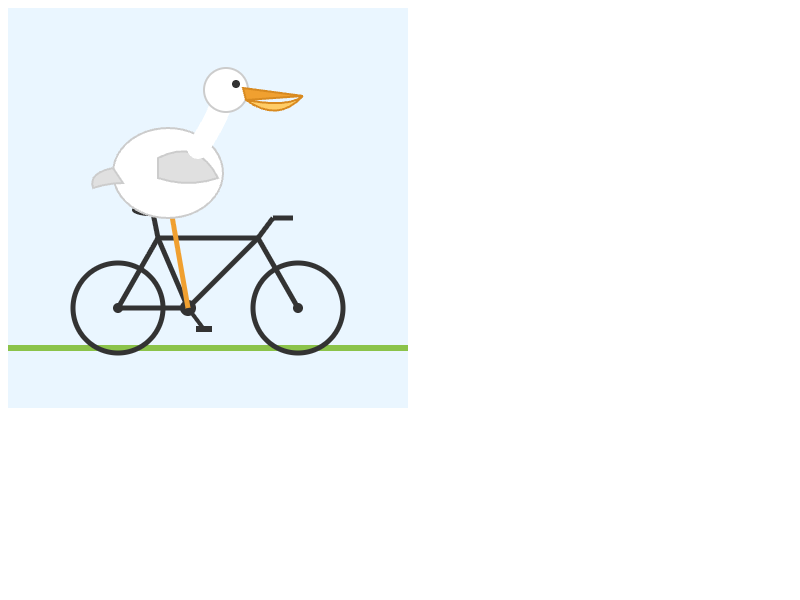
Oct 1, 2026 · 18 s · $0.04
Test details
- Run date
- Oct 1, 2026
- API provider
- openrouter
- Requested API model
- anthropic/claude-opus-4.8
- Reasoning setting
- high
- Token limit including reasoning
- 8,192 tokens
- Output tokens
- 1,659 tokens
- Cost of the attempt
- $0.0416
- Response time
- 18 s
- API model reported in response
- anthropic/claude-opus-4.8
- Pinned endpoint
- Anthropic | anthropic/claude-4.8-opus-20260528
- Temperature
- Provider default
- Test protocol
- community-visual-tests-v1
- Technical checks
- Passed, not a quality rating
Visually reviewed. This individual test does not establish overall model quality.
GPT-6.2 Sol
Not tested yet
SVG short test
There is no shared test round for this selection. Results from different rounds are not mixed.
Claude Opus 4.8 and GPT-6.2 Sol in the overall index
Every model with a place in the overall index, both models of this matchup highlighted. You can add or hide other models.
Overall index (Gradually Meta-Score v6)
20 of 99 models
All data side by side
The better value is bold. For the overall index only when the gap is clear.
| Metric | Claude Opus 4.8 | GPT-6.2 Sol |
|---|---|---|
| Intelligence | ||
| Overall indexpoints, 100 = reference group average, higher is better | 99.3 | 119.2 |
| Rank | Rank 36 of 99 | Rank 10 of 99 |
| Price per 1M tokens | ||
| Inputwhat you send | $5 | $2above 272,000 input tokens: $4 |
| Outputwhat the model writes | $25 | $10above 272,000 input tokens: $15 |
| Speed | ||
| Tokens per second | 67 | n/a |
| Technical | ||
| Context windowsource-reported context limit | 1 M tokens≈ 1,500 A4 pages | 1.05 M tokens≈ 1,580 A4 pages |
| Knowledge cutoff | January 2026 | Jun 1, 2026 |
| Released | May 2026 | Nov 17, 2026 |
| Availability | Legacy | Active |
| Open weights | no | no |
- GPT-6.2 Sol, 12-hour cache write price: The table lists the 30-minute rate. For 12-hour retention, OpenAI charges $5 per 1M tokens at the Standard rate through 272,000 input tokens. Source
- GPT-6.2 Sol, Long-context pricing: Above 272,000 input tokens, the higher rates apply to the entire request. Source
- GPT-6.2 Sol, Batch, Fast, and Ultrafast: Batch costs half the Standard rate and Fast costs twice the Standard rate. Ultrafast costs three times the Standard rate through February 28, 2027 and six times the rate from March 1, 2027. The change follows Pacific time. Source
Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis
Is there a better choice?
Overall index 117.1, rank 13$5 input and $25 output per 1M tokens
GPT-6.2 Sol vs. Claude Opus 5Overall index 127.8, rank 2$2 input and $10 output per 1M tokens
GPT-6.2 Sol vs. Gemini 4 CarbonOverall index 130.3, rank 1$8 input and $40 output per 1M tokens
GPT-6.2 Sol vs. Claude Fable 5.2Shared benchmarks
Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.
A: Claude Opus 4.8B: GPT-6.2 Sol
More comparisons
Compare Claude Opus 4.8 and GPT-6.2 Sol with the models people compare them with most often.
Compare another matchup
Predecessor and successor
The most popular comparisons
- 1GPT-6.2 Astra vs. GPT-6.2 Sol
- 2Claude Opus 5.5 vs. GPT-6.2 Sol
- 3GPT-6.2 Sol vs. GLM-5.3
- 4Claude Fable 5.2 vs. GPT-6.2 Sol
- 5GPT-6.2 Sol vs. GPT-6.1 Terra
- 6Claude Opus 5.5 vs. Claude Opus 4.8
- 7Claude Opus 4.8 vs. GPT-6.1 Sol
- 8Claude Opus 4.8 vs. GPT-6 Luna
- 9Claude Opus 4.8 vs. GLM-5.3-Flash
Show all 27 comparisons
- 10Claude Haiku 5.5 vs. Claude Opus 4.8
- 11Claude Opus 4.8 vs. DeepSeek V4.1 Flash 1017
- 12Claude Opus 4.8 vs. DeepSeek-V4.1-Flash
- 13Claude Opus 4.8 vs. Grok 4.7
- 14Claude Opus 4.8 vs. GPT-6 Sol
- 15Claude Opus 4.8 vs. GPT-6 Astra
- 16Claude Opus 4.8 vs. Qwen 3.8 27B
- 17Claude Sonnet 5.5 vs. Claude Opus 4.8
- 18Claude Opus 4.8 vs. GPT-6.1 Terra
- 19Claude Opus 4.8 vs. Gemini 4 Carbon
- 20Claude Opus 4.8 vs. Gemini 3.8 Flash
- 21Claude Opus 4.8 vs. DeepSeek-V4-Flash
- 22Claude Opus 4.8 vs. Kimi K3.1 Pro
- 23Claude Opus 4.8 vs. Qwen 3.8 Max 0902
- 24Claude Opus 4.8 vs. Mistral Large 4
- 25Claude Opus 4.8 vs. GPT-5.5
- 26Claude Opus 4.8 vs. Gemini 4 Argon
- 27GPT-6.2 Sol vs. Gemini 4 Neon