
Head-to-head comparison

Claude Opus 4.5 vs. Muse Wonder Full

Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.

shared result series
8
distinct benchmarks
3
latest retrieval
2026-10-15

Change model selection

Specifications

General specifications

Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.

Specifications for Claude Opus 4.5 and Muse Wonder Full
AttributeClaude Opus 4.5Muse Wonder Full
ProviderAnthropicMeta
ReleasedNov 2025Oct 12, 2026
AvailabilityActiveSubscription only
Model typeProprietaryProprietary
ParametersNot publishedNot published
ArchitectureNot publishedNot published
Context window200,000 tokens1M tokens
Knowledge cutoffMay 2025Not published
Technical sourcesModel, ContextModel, Context

Pricing

API pricing compared

The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.

API pricing for Claude Opus 4.5 and Muse Wonder Full
Price typeClaude Opus 4.5Muse Wonder Full
API input$5—
API output$25—
Cache read$0.5Not listed
Cache write (5 min.)$6.25Not listed
Cache write (1 hr.)$10Not listed
Price verified09/22/2026 Source10/15/2026
Pricing by provider

Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.

No provider tariff for Muse Wonder Full is available in the stored OpenRouter snapshot. The official direct price is still shown.

Provider pricing for Claude Opus 4.5 and Muse Wonder Full
ModelProviderPurchase route and tariffInput per 1M tokensOutput per 1M tokensSource
Claude Opus 4.5AnthropicDirect from developerStandard APILowest listed price: $5Lowest listed price: $25Source09/22/2026
Amazon BedrockVia OpenRouteramazon-bedrockLowest listed price: $5Lowest listed price: $25Source10/16/2026
Amazon BedrockVia OpenRouteramazon-bedrock/eu-west-1$5.5$27.5Source10/16/2026
AnthropicVia OpenRouteranthropicLowest listed price: $5Lowest listed price: $25Source10/16/2026
AzureVia OpenRouterazure/globalLowest listed price: $5Lowest listed price: $25Source10/16/2026
Claude Platform on AWSVia OpenRouterclaude-on-awsLowest listed price: $5Lowest listed price: $25Source10/16/2026
GoogleVia OpenRoutergoogle-vertex/globalLowest listed price: $5Lowest listed price: $25Source10/16/2026

Performance

Shared benchmarks

Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.

Capability profile from matched benchmarks

Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.

Not enough directly matched categories for a reliable radar

Only 0 of at least 5 categories have comparable, direct model measurements. The benchmark tables below show the available evidence without filling missing axes.

Claude Opus 4.5Muse Wonder Full
LegalBenchOverall. Higher is better. Test setup not documented as identical
Claude Opus 4.582.837 %
Muse Wonder FullHigher measured value87.418 %
MedCodeOverall. Higher is better. Test setup not documented as identical
Claude Opus 4.545.174 %
Muse Wonder FullHigher measured value49.932 %
MedScribeOverall. Higher is better. Test setup not documented as identical
Claude Opus 4.583.246 %
Muse Wonder FullHigher measured value89.335 %
LegalBenchConclusion Tasks. Higher is better. Test setup not documented as identical
Claude Opus 4.587.7 %
Muse Wonder FullHigher measured value90.323 %
LegalBenchInterpretation Tasks. Higher is better. Test setup not documented as identical
Claude Opus 4.582.235 %
Muse Wonder FullHigher measured value84.991 %
LegalBenchIssue Tasks. Higher is better. Test setup not documented as identical
Claude Opus 4.584.152 %
Muse Wonder FullHigher measured value91.014 %
LegalBenchRhetoric Tasks. Higher is better. Test setup not documented as identical
Claude Opus 4.579.777 %
Muse Wonder FullHigher measured value83.625 %
LegalBenchRule Tasks. Higher is better. Test setup not documented as identical
Claude Opus 4.580.32 %
Muse Wonder FullHigher measured value87.136 %

Key to the marks:better valuebetter, but not conclusivetie

Benchmark scores for Claude Opus 4.5 and Muse Wonder Full
Benchmark and taskClaude Opus 4.5Muse Wonder FullSource
LegalBenchOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.5: Snapshot: claude-opus-4-5-20251101, Compute: high, Temperature: 1, Output limit: 64,000 tokens
Muse Wonder Full: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
82.837 %
Higher measured value87.418 %
Vals AI
Source details
Data as of: 10/13/2026
MedCodeOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.5: Snapshot: claude-opus-4-5-20251101, Compute: high, Temperature: 1, Output limit: 30,000 tokens
Muse Wonder Full: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
45.174 %
Higher measured value49.932 %
Vals AI
Source details
Data as of: 10/13/2026
MedScribeOverall
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.5: Snapshot: claude-opus-4-5-20251101, Compute: high, Temperature: 1, Output limit: 30,000 tokens
Muse Wonder Full: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
83.246 %
Higher measured value89.335 %
Vals AI
Source details
Data as of: 10/13/2026
LegalBenchConclusion Tasks
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.5: Snapshot: claude-opus-4-5-20251101, Compute: high, Temperature: 1, Output limit: 64,000 tokens
Muse Wonder Full: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
87.7 %
Higher measured value90.323 %
Vals AI
Source details
Data as of: 10/13/2026
LegalBenchInterpretation Tasks
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.5: Snapshot: claude-opus-4-5-20251101, Compute: high, Temperature: 1, Output limit: 64,000 tokens
Muse Wonder Full: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
82.235 %
Higher measured value84.991 %
Vals AI
Source details
Data as of: 10/13/2026
LegalBenchIssue Tasks
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.5: Snapshot: claude-opus-4-5-20251101, Compute: high, Temperature: 1, Output limit: 64,000 tokens
Muse Wonder Full: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
84.152 %
Higher measured value91.014 %
Vals AI
Source details
Data as of: 10/13/2026
LegalBenchRhetoric Tasks
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.5: Snapshot: claude-opus-4-5-20251101, Compute: high, Temperature: 1, Output limit: 64,000 tokens
Muse Wonder Full: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
79.777 %
Higher measured value83.625 %
Vals AI
Source details
Data as of: 10/13/2026
LegalBenchRule Tasks
Test details
Test setup not documented as identicalNo direct winnerVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.5: Snapshot: claude-opus-4-5-20251101, Compute: high, Temperature: 1, Output limit: 64,000 tokens
Muse Wonder Full: Reasoning: max, Temperature: 1, Output limit: 131,072 tokens
80.32 %
Higher measured value87.136 %
Vals AI
Source details
Data as of: 10/13/2026

Key to the marks:better valuebetter, but not conclusivetie

Our model tests

Our tests

There is no shared test round for this selection. Results from different rounds are not mixed.

Earlier tests

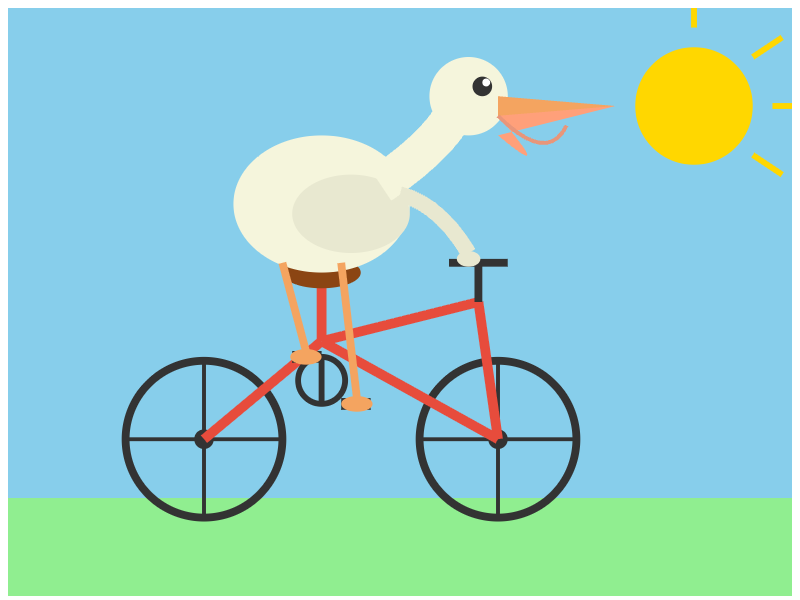
Pelican on a bicycle

A community classic for free-form SVG drawing.

Claude Opus 4.5

Claude Opus 4.5: Pelican on a bicycle
A community classic for free-form SVG drawing.

Reasoning (requested): high

Current attempt
Run date
Oct 1, 2026
API provider
openrouter
Requested API model
anthropic/claude-opus-4.5
API model reported in response
anthropic/claude-opus-4.5
Reasoning setting
high
Pinned endpoint
Anthropic | anthropic/claude-4.5-opus-20251124
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
21.6 s

Visually reviewed. This individual test does not establish overall model quality.

Muse Wonder Full

Not tested yet

Prompt and test conditions

Generate an SVG of a pelican riding a bicycle

Token limit including reasoning: 8,192 tokens

Task origin (Simon Willison)

How to read this comparison

Winning one benchmark is not an overall verdict

Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.

The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.

Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.

More matchups

Compare Claude Opus 4.5 and Muse Wonder Full with other leading models using the same data and benchmark logic.
View the complete LLM comparison