Qwen 3.8 27Bvs.MiMo-V2.5
Which one is better?
Qwen 3.8 27B is clearly ahead in the overall index. Qwen 3.8 27B is cheaper for input, MiMo-V2.5 for output.
Qwen 3.8 27B
Rank 44 to 57
MiMo-V2.5
Rank 60 to 69
Qwen 3.8 27B
slow
MiMo-V2.5
fairly slow
Qwen 3.8 27B
fairly cheap
MiMo-V2.5
cheap
Qwen 3.8 27B
- Subscription
No Alibaba subscription includes this model. Through other providers from ≈ €1.06 a month (Command Code Go, with limited credits). 10 plans in Germany.
- Via API
$0.04 input, $2.50 output per 1M tokens according to the provider; the price index has listed it at $0.42 and $3 since Oct 27, 2026.
MiMo-V2.5
- Subscription
No Xiaomi subscription includes this model. Through other providers from ≈ €1.06 a month (Command Code Go, with limited credits). 10 plans in Germany.
- Via API
$0.14 input, $0.28 output per 1M tokens, cheaper since Oct 26, 2026 (before $0.168 and $0.336).
Overall index with data through Oct 29, 2026 · Prices from Oct 29, 2026 · Speed: measured by Artificial Analysis · Subscriptions as of Oct 24, 2026 · Subscription prices incl. VAT
Where is the difference?
Values from 0 to 100 per task area. We only name a winner when the gap is large enough and there are enough tests.
Qwen 3.8 27B ahead: 7MiMo-V2.5 ahead: 0level: 2too little data: 1of 10 areas
Show 1 more areas that do not count toward the overall index
See for yourself: same task, one attempt
SVG short test
One SVG task with the same fixed settings for every model, without hidden thinking.
Shared test round: 43b8c5c46830
Qwen 3.8 27B
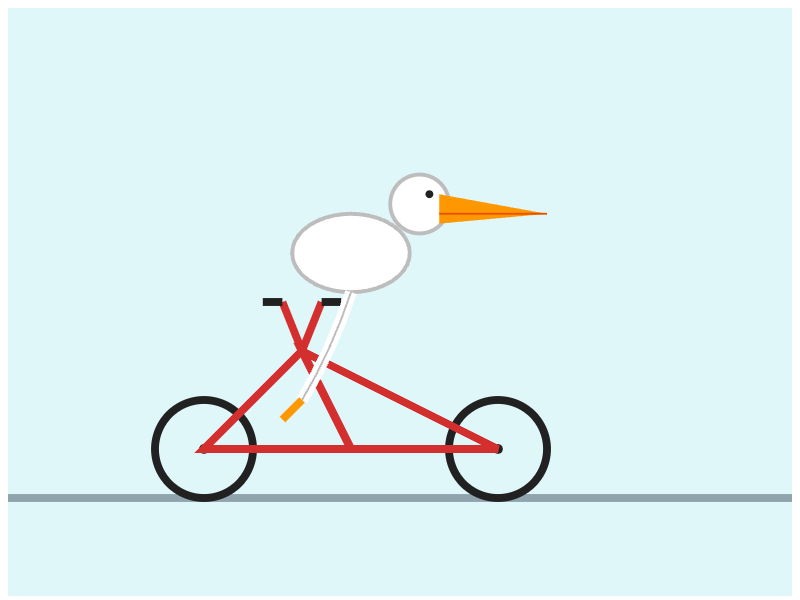
Test details
API reports 0 reasoning tokensAPI model: qwen/qwen3.8-27b865 output tokensMiMo-V2.5
API request failed. The model was not evaluated.
Earlier tests
Pelican on a bicycle
A community classic for free-form SVG drawing.
Qwen 3.8 27B
Not tested yet
MiMo-V2.5
The response reached the token limit. No complete recording is available.
Reasoning (requested): high
Current attempt
- Run date
- Oct 5, 2026
- API provider
- openrouter
- Requested API model
- xiaomi/mimo-v2.5
- API model reported in response
- xiaomi/mimo-v2.5
- Reasoning setting
- high
- Pinned endpoint
- Xiaomi | xiaomi/mimo-v2.5-20260422
- Temperature
- Provider default
- Token limit including reasoning
- 8,192 tokens
- Test protocol
- community-visual-tests-v1
- Technical checks
- Failed
- Response time
- 136.3 s
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Earlier attempts (3)
- Oct 2, 2026API request failedReasoning setting: high
- Oct 1, 2026API request failedReasoning setting: high
- Sep 7, 2026API request failedReasoning setting: high
Prompt and test conditions
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)All data side by side
The better value is bold. For the overall index only when the gap is clear.
| Metric | Qwen 3.8 27B | MiMo-V2.5 |
|---|---|---|
| Intelligence | ||
| Overall index0 to 100, higher is better | 11 | 2 |
| Rank | Rank 44 to 57 of 95 | Rank 60 to 69 of 95 |
| Price per 1M tokens | ||
| Inputwhat you send | $0.04 | $0.14 |
| Outputwhat the model writes | $2.50 | $0.28 |
| Speed | ||
| Tokens per second | 40 | 72 |
| Technical | ||
| Context windowhow much text the model reads at once | 262,144 tokens≈ 390 A4 pages | 1 M tokens≈ 1,500 A4 pages |
| Knowledge cutoff | n/a | n/a |
| Released | Aug 14, 2026 | Apr 23, 2026 |
| Availability | Active | Open Source |
| Open weights | yes | yes |
Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis
Shared benchmarks
Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.
A: Qwen 3.8 27BB: MiMo-V2.5