Gemini 3.6 Flashvs.Qwen 3.8 27B
Which one is better?
Gemini 3.6 Flash is clearly ahead in the overall index, but costs 18.8 times (input) and 1.5 times (output) as much per token.
Gemini 3.6 Flash
Rank 24 to 38
Qwen 3.8 27B
Rank 44 to 57
Gemini 3.6 Flash
fast
Qwen 3.8 27B
slow
Gemini 3.6 Flash
fairly cheap
Qwen 3.8 27B
fairly cheap
Gemini 3.6 Flash
- Subscription
Free to use at Google (Google AI Free, with limited credits), more from €4.99 a month (Google AI Plus, with limited credits). Through other providers from ≈ €6.36 a month (ElevenLabs Starter, with limited credits). 42 plans in Germany.
- Via API
$0.75 input, $3.75 output per 1M tokens, unchanged since our price tracking began on Aug 14, 2026.
- Note
- There is a successor: Gemini 3.7 Flash (rank 14 to 20, same price).
Qwen 3.8 27B
- Subscription
No Alibaba subscription includes this model. Through other providers from ≈ €1.06 a month (Command Code Go, with limited credits). 10 plans in Germany.
- Via API
$0.04 input, $2.50 output per 1M tokens according to the provider; the price index has listed it at $0.42 and $3 since Oct 27, 2026.
Overall index with data through Oct 29, 2026 · Prices from Oct 29, 2026 · Speed: measured by Artificial Analysis · Subscriptions as of Oct 24, 2026 · Subscription prices incl. VAT
Where is the difference?
Values from 0 to 100 per task area. We only name a winner when the gap is large enough and there are enough tests.
Gemini 3.6 Flash ahead: 5Qwen 3.8 27B ahead: 0level: 3too little data: 2of 10 areas
Show 2 more areas that do not count toward the overall index
See for yourself: same task, one attempt
The same prompt for both models. We show the latest attempt without fixes; it does not count toward the overall index.
Pelican on a bicycle
A community classic for free-form SVG drawing.
Gemini 3.6 Flash
The response reached the token limit. No complete recording is available.
Reasoning (requested): high
Current attempt
- Run date
- Oct 5, 2026
- API provider
- openrouter
- Requested API model
- google/gemini-3.6-flash
- API model reported in response
- google/gemini-3.6-flash
- Reasoning setting
- high
- Pinned endpoint
- Google AI Studio | google/gemini-3.6-flash-20260721
- Temperature
- Provider default
- Token limit including reasoning
- 8,192 tokens
- Test protocol
- community-visual-tests-v1
- Technical checks
- Failed
- Response time
- 39.6 s
Not yet visually reviewed. A successful recording does not confirm correct physics or full compliance with the prompt.
Earlier attempts (3)
- Oct 2, 2026API request failedReasoning setting: high
- Oct 1, 2026API request failedReasoning setting: high
- Sep 7, 2026API request failedReasoning setting: high
Qwen 3.8 27B
Not tested yet
Prompt and test conditions
Generate an SVG of a pelican riding a bicycle
Token limit including reasoning: 8,192 tokens
Task origin (Simon Willison)SVG short test
SVG short test
One SVG task with the same fixed settings for every model, without hidden thinking.
Shared test round: 43b8c5c46830
Gemini 3.6 Flash
Unavailable in this round
Qwen 3.8 27B
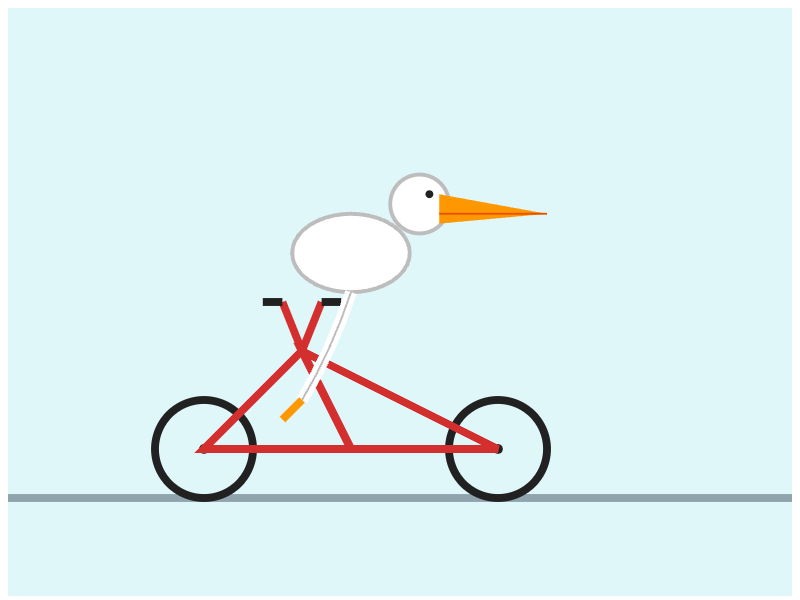
Test details
API reports 0 reasoning tokensAPI model: qwen/qwen3.8-27b865 output tokensAll data side by side
The better value is bold. For the overall index only when the gap is clear.
| Metric | Gemini 3.6 Flash | Qwen 3.8 27B |
|---|---|---|
| Intelligence | ||
| Overall index0 to 100, higher is better | 42 | 11 |
| Rank | Rank 24 to 38 of 95 | Rank 44 to 57 of 95 |
| Price per 1M tokens | ||
| Inputwhat you send | $0.75 | $0.04 |
| Outputwhat the model writes | $3.75 | $2.50 |
| Speed | ||
| Tokens per second | 202 | 40 |
| Technical | ||
| Context windowhow much text the model reads at once | 1.05 M tokens≈ 1,570 A4 pages | 262,144 tokens≈ 390 A4 pages |
| Knowledge cutoff | March 2026 | n/a |
| Released | Jul 21, 2026 | Aug 14, 2026 |
| Availability | Active | Active |
| Open weights | no | yes |
Prices without caching or batch discounts · Page count as a rule of thumb from Artificial Analysis
Shared benchmarks
Single results from the same benchmark version, task and metric. A value is bold only with the same test setup and a clear gap.
A: Gemini 3.6 FlashB: Qwen 3.8 27B
Show 54 more benchmarks
Compare another matchup
More matchups
Related LLM comparisons
Compare Gemini 3.6 Flash and Qwen 3.8 27B with other leading models.