Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.
shared result series
12
distinct benchmarks
9
latest retrieval
2026-09-29
Change model selection
Specifications
General specifications
Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.
The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.
Key to the marks:better valuebetter, but not conclusivetie
Pricing by provider
Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.
Provider pricing for Claude Sonnet 4.5 and GPT-5.4
Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.
Capability profile from matched benchmarks
Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.
Not enough directly matched categories for a reliable radar
Only 3 of at least 5 categories have comparable, direct model measurements. The benchmark tables below show the available evidence without filling missing axes.
Claude Sonnet 4.5GPT-5.4
CorpFin v2Overall. Higher is better. No documented setup difference
Claude Sonnet 4.560.8 %
GPT-5.4Winner65.268 %
MedCodeOverall. Higher is better. No documented setup difference
Claude Sonnet 4.540.569 %
GPT-5.4Winner41.292 %
MedScribeOverall. Higher is better. No documented setup difference
Claude Sonnet 4.5Winner84.515 %
GPT-5.477.549 %
MultiNRCOverall. Higher is better. Test setup not documented as identical
Claude Sonnet 4.528.15% ± 2.71
GPT-5.4Higher measured value58.29% ± 2.98
PRBench FinanceOverall. Higher is better. Test setup not documented as identical
Claude Sonnet 4.543.79% ± 0.4
GPT-5.4Higher measured value45.63% ± 0.56
PRBench LegalOverall. Higher is better. Test setup not documented as identical
Claude Sonnet 4.540.84% ± 0.4
GPT-5.4Higher measured value44.35% ± 0.28
SAGEOverall. Higher is better. No documented setup difference
Claude Sonnet 4.532.88 %
GPT-5.4Winner43.312 %
VISTAOverall. Higher is better. Test setup not documented as identical
Claude Sonnet 4.545% ± 0.12
GPT-5.4Higher measured value50.89% ± 1.76
VisualToolBenchOverall. Higher is better. Test setup not documented as identical
Claude Sonnet 4.55.6% ± 0.12
GPT-5.4Higher measured value29.17% ± 0.13
MultiNRCOverall. Higher is better. Test setup not documented as identical
Claude Sonnet 4.535.83% ± 2.89
GPT-5.4Higher measured value58.29% ± 2.98
VISTAOverall. Higher is better. Test setup not documented as identical
Claude Sonnet 4.548.75% ± 1.67
GPT-5.4Higher measured value50.89% ± 1.76
VisualToolBenchOverall. Higher is better. Test setup not documented as identical
Claude Sonnet 4.56.2% ± 0.14
GPT-5.4Higher measured value29.17% ± 0.13
Key to the marks:better valuebetter, but not conclusivetie
Benchmark scores for Claude Sonnet 4.5 and GPT-5.4
No documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterClaude Sonnet 4.5: Snapshot: claude-sonnet-4-5-20250929 GPT-5.4: Snapshot: gpt-5.4-2026-03-05
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.5: Snapshot: claude-sonnet-4-5-20250929 GPT-5.4: Snapshot: gpt-5.4-2026-03-05
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.5: Snapshot: claude-sonnet-4-5-20250929 GPT-5.4: Snapshot: gpt-5.4-2026-03-05
Test setup not documented as identicalNo direct winnerVersion: French, Spanish, and Chinese releaseMetric: accuracyScoring: Higher is betterClaude Sonnet 4.5: Attempts: pass@1 GPT-5.4: Snapshot: gpt-5.4-xhigh, Reasoning: xhigh, Attempts: pass@1Native, non-translated reasoning tasks with automatic evaluation.
Test setup not documented as identicalNo direct winnerVersion: full finance setMetric: weighted rubric scoreScoring: Higher is betterClaude Sonnet 4.5: Attempts: pass@1 GPT-5.4: Snapshot: gpt-5.4-high, Reasoning: high, Attempts: pass@1600 finance tasks with task-specific rubrics and o4-mini as judge.
Test setup not documented as identicalNo direct winnerVersion: full legal setMetric: weighted rubric scoreScoring: Higher is betterClaude Sonnet 4.5: Attempts: pass@1 GPT-5.4: Snapshot: gpt-5.4-high, Reasoning: high, Attempts: pass@1500 legal tasks with task-specific rubrics and o4-mini as judge.
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterClaude Sonnet 4.5: Snapshot: claude-sonnet-4-5-20250929 GPT-5.4: Snapshot: gpt-5.4-2026-03-05
Test setup not documented as identicalNo direct winnerVersion: 1,204-task releaseMetric: average pass rateScoring: Higher is betterClaude Sonnet 4.5: Attempts: pass@1 GPT-5.4: Snapshot: gpt-5.4-high, Reasoning: high, Attempts: pass@11,204 tasks, six tools, and at most 20 tool calls per task.
Test setup not documented as identicalNo direct winnerVersion: French, Spanish, and Chinese releaseMetric: accuracyScoring: Higher is betterClaude Sonnet 4.5: Reasoning: thinking, Attempts: pass@1 GPT-5.4: Snapshot: gpt-5.4-xhigh, Reasoning: xhigh, Attempts: pass@1Native, non-translated reasoning tasks with automatic evaluation.
Test setup not documented as identicalNo direct winnerVersion: 1,204-task releaseMetric: average pass rateScoring: Higher is betterClaude Sonnet 4.5: Reasoning: thinking, Attempts: pass@1 GPT-5.4: Snapshot: gpt-5.4-high, Reasoning: high, Attempts: pass@11,204 tasks, six tools, and at most 20 tool calls per task.
Key to the marks:better valuebetter, but not conclusivetie
Our model tests
Our tests
Compare how the models respond to the same prompt. Each test shows the latest attempt, with no subsequent fixes to the generated code. Earlier runs remain available in the test details. These results do not contribute to an overall score.
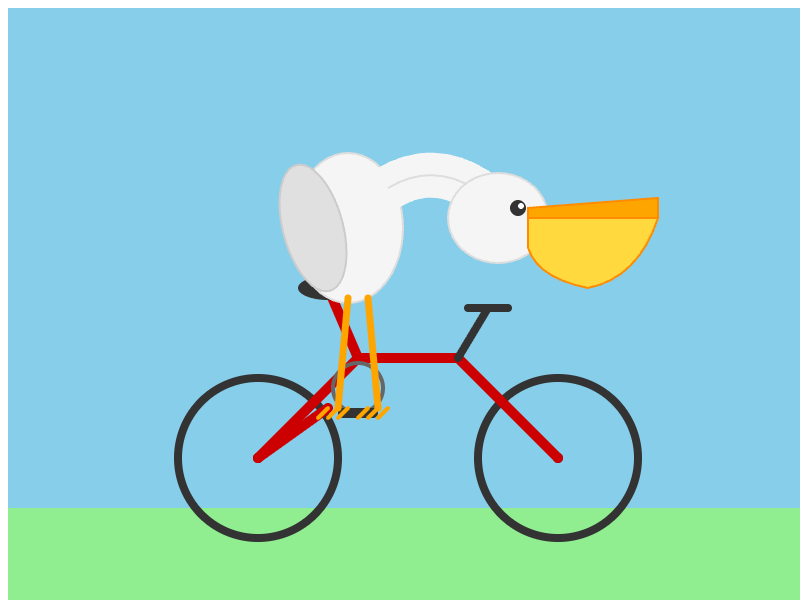
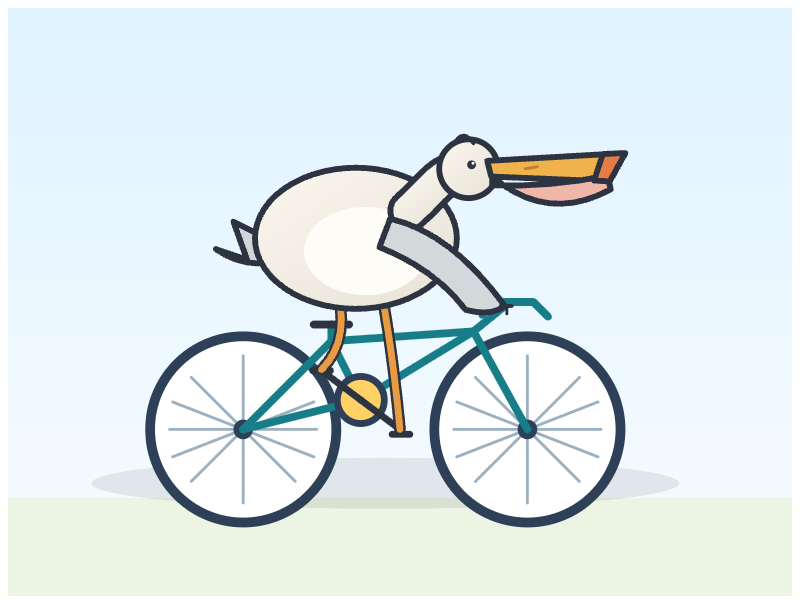
Pelican on a bicycle
A community classic for free-form SVG drawing.
Claude Sonnet 4.5
A community classic for free-form SVG drawing.
Reasoning (requested): high
Current attempt
Run date
1 Oct 2026
API provider
openrouter
Requested API model
anthropic/claude-sonnet-4.5
API model reported in response
anthropic/claude-sonnet-4.5
Reasoning setting
high
Pinned endpoint
Anthropic | anthropic/claude-4.5-sonnet-20250929
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
30.2 s
Visually reviewed. This individual test does not establish overall model quality.
GPT-5.4
A community classic for free-form SVG drawing.
Reasoning (requested): high
Current attempt
Run date
1 Oct 2026
API provider
openrouter
Requested API model
openai/gpt-5.4
API model reported in response
openai/gpt-5.4
Reasoning setting
high
Pinned endpoint
OpenAI | openai/gpt-5.4-20260305
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
116.8 s
Visually reviewed. This individual test does not establish overall model quality.
Earlier attempts (1)
7 Sept 2026API request failedReasoning setting: high
Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.
The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.
Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.
More matchups
Related LLM comparisons
Compare Claude Sonnet 4.5 and GPT-5.4 with other leading models using the same data and benchmark logic.