Head-to-head comparison

Claude Opus 4.8 vs. GPT-5.4

Compare published benchmark results from matching versions and cohorts, API pricing, and technical specifications. Any documented test setup differences remain visible.

shared result series
18
distinct benchmarks
18
latest retrieval
2026-09-29

Change model selection

Specifications

General specifications

Release date, availability, context window, architecture, and published parameter counts at a glance. Undisclosed details remain marked as unavailable.

Specifications for Claude Opus 4.8 and GPT-5.4
AttributeClaude Opus 4.8GPT-5.4
ProviderAnthropicOpenAI
ReleasedMay 2026Mar 5, 2026
AvailabilityLegacyActive
Model typeProprietaryProprietary
ParametersNot publishedNot published
ArchitectureNot publishedNot published
Context window1,000,000 tokens1,050,000 tokens
Knowledge cutoffJanuary 2026August 31, 2025
Technical sourcesModel, Knowledge cutoffModel

Pricing

API pricing compared

The table compares official standard API rates per 1M tokens, including published cache pricing. Batch, fast, priority, regional surcharges, tool calls, and cloud platform pricing are excluded.

API pricing for Claude Opus 4.8 and GPT-5.4
Price typeClaude Opus 4.8GPT-5.4
API input$5$2.5 ≤272K / $5 >272K
API output$25$15 ≤272K / $22.5 >272K
Cache read$0.5$0.25 ≤272K / $0.5 >272K
Cache write (5 min.)$6.25Not listed
Cache write (1 hr.)$10Not listed
Price verified09/22/2026 Source09/22/2026 Source
Claude Opus 4.8GPT-5.4
API inputUSD per 1M tokens, base tier
Claude Opus 4.8$5
GPT-5.4Lower price$2.5
API outputUSD per 1M tokens, base tier
Claude Opus 4.8$25
GPT-5.4Lower price$15
Cache readUSD per 1M tokens, base tier
Claude Opus 4.8$0.5
GPT-5.4Lower price$0.25

Key to the marks:better valuebetter, but not conclusivetie

Pricing by provider

Direct developer pricing and provider endpoint tariffs routed through OpenRouter are listed separately. Prices are in USD per 1M tokens. Context-dependent direct tiers plus regional, Flex, Priority, and other OpenRouter tariffs remain individually identifiable.

No provider tariff for Claude Opus 4.8 is available in the stored OpenRouter snapshot. The official direct price is still shown.

Provider pricing for Claude Opus 4.8 and GPT-5.4
ModelProviderPurchase route and tariffInput per 1M tokensOutput per 1M tokensSource
Claude Opus 4.8AnthropicDirect from developerStandard APILowest listed price: $5Lowest listed price: $25Source09/22/2026
GPT-5.4OpenAIDirect from developerUp to 272,000 context tokens$2.5$15Source09/22/2026
OpenAIDirect from developerAbove 272,000 context tokens$5$22.5Source09/22/2026
Amazon BedrockVia OpenRouteramazon-bedrock/us-east-1$2.75$16.5Source10/07/2026
AzureVia OpenRouterazure$2.5$15Source10/07/2026
AzureVia OpenRouterazure/eu$2.75$16.5Source10/07/2026
AzureVia OpenRouterazure/us$2.75$16.5Source10/07/2026
OpenAIVia OpenRouteropenai$2.5$15Source10/07/2026
OpenAIVia OpenRouteropenai/fast$5$30Source10/07/2026
OpenAIVia OpenRouteropenai/flexLowest listed price: $1.25Lowest listed price: $7.5Source10/07/2026

Performance

Shared benchmarks

Only published results with the same benchmark version, task, metric, and comparison cohort are paired. Different reasoning levels, agents, harnesses, or output limits appear directly in the table.

Capability profile from matched benchmarks

Each axis averages directly matched benchmark families. A value of 100 means the stronger value within this pair, not a universal quality score.

255075100CodingReasoningKnowledgeFinanceLegalAgentic tasksMultimodalHealth
Claude Opus 4.8
GPT-5.4
Coding: 100 / 67.9 (5 benchmark families)
Reasoning: 100 / 99.2 (1 benchmark family)
Knowledge: 100 / 97.7 (1 benchmark family)
Finance: 100 / 97.8 (3 benchmark families)
Legal: 98.6 / 50 (2 benchmark families)
Agentic tasks: 100 / 85.4 (2 benchmark families)
Multimodal: 98.9 / 100 (1 benchmark family)
Health: 100 / 84 (2 benchmark families)

18 matched rows from 18 benchmark families were considered. The radar shows 8 of 9 comparable categories.

Claude Opus 4.8GPT-5.4
Code MigrationOverall. Higher is better. No documented setup difference
Claude Opus 4.8Winner47.25 %
GPT-5.434.984 %
CorpFin v2Overall. Higher is better. No documented setup difference
Claude Opus 4.8Winner66.706 %
GPT-5.465.268 %
GPQA DiamondOverall. Higher is better. No documented setup difference
Claude Opus 4.8Winner92.424 %
GPT-5.491.666 %
Harvey's Legal Agent BenchmarkOverall · Task fully resolved. Higher is better. No documented setup difference
Claude Opus 4.8Winner9.583 %
GPT-5.40 %
LegalBenchOverall. Higher is better. No documented setup difference
Claude Opus 4.883.568 %
GPT-5.4Winner86.044 %
LiveCodeBench v6Overall. Higher is better. No documented setup difference
Claude Opus 4.8Winner87.819 %
GPT-5.484.141 %
MedCodeOverall. Higher is better. No documented setup difference
Claude Opus 4.8Winner53.217 %
GPT-5.441.292 %
MedScribeOverall. Higher is better. No documented setup difference
Claude Opus 4.8Winner85.755 %
GPT-5.477.549 %
MMLU-ProOverall. Higher is better. No documented setup difference
Claude Opus 4.8Winner89.585 %
GPT-5.487.482 %
MMMU-ProOverall. Higher is better. No documented setup difference
Claude Opus 4.886.59 %
GPT-5.4Winner87.514 %
MortgageTaxOverall. Higher is better. No documented setup difference
Claude Opus 4.8Winner69.912 %
GPT-5.468.323 %
ProgramBenchOverall. Higher is better. No documented setup difference
Claude Opus 4.8Winner1 %
GPT-5.40 %

Key to the marks:better valuebetter, but not conclusivetie

Benchmark scores for Claude Opus 4.8 and GPT-5.4
Benchmark and taskClaude Opus 4.8GPT-5.4Source
Code MigrationOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner47.25 %
34.984 %
Vals AI
Source details
Data as of: 09/27/2026
CorpFin v2Overall
Test details
No documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner66.706 %
65.268 %
Vals AI
Source details
Data as of: 08/12/2026
GPQA DiamondOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner92.424 %
91.666 %
Vals AI
Source details
Data as of: 09/01/2026
Harvey's Legal Agent BenchmarkOverall · Task fully resolved
Test details
No documented difference in the test setupVersion: 1Metric: task resolution rateScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner9.583 %
0 %
Vals AI
Source details
Data as of: 09/27/2026
LegalBenchOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
83.568 %
Winner86.044 %
Vals AI
Source details
Data as of: 09/27/2026
LiveCodeBench v6Overall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner87.819 %
84.141 %
Vals AI
Source details
Data as of: 09/01/2026
MedCodeOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner53.217 %
41.292 %
Vals AI
Source details
Data as of: 09/26/2026
MedScribeOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner85.755 %
77.549 %
Vals AI
Source details
Data as of: 09/26/2026
MMLU-ProOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner89.585 %
87.482 %
Vals AI
Source details
Data as of: 09/01/2026
MMMU-ProOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
86.59 %
Winner87.514 %
Vals AI
Source details
Data as of: 09/01/2026
MortgageTaxOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner69.912 %
68.323 %
Vals AI
Source details
Data as of: 09/01/2026
ProgramBenchOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner1 %
0 %
Vals AI
Source details
Data as of: 09/27/2026
SAGEOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner54.788 %
43.312 %
Vals AI
Source details
Data as of: 09/26/2026
SkillsBenchOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterClaude Opus 4.8: Harness: OpenHands
GPT-5.4: Snapshot: gpt-5.4-2026-03-05, Harness: OpenHands
Winner59.227 %
51.711 %
Vals AI
Source details
Data as of: 09/27/2026
SWE-bench VerifiedOverall
Test details
No documented difference in the test setupVersion: 1Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner88.6 %
78.2 %
Vals AI
Source details
Data as of: 09/01/2026
TaxEval v2Overall
Test details
No documented difference in the test setupVersion: 2Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner75.634 %
73.958 %
Vals AI
Source details
Data as of: 09/01/2026
Terminal-Bench 2.0Overall
Test details
No documented difference in the test setupVersion: 2.0Metric: accuracyScoring: Higher is betterGPT-5.4: Snapshot: gpt-5.4-2026-03-05
Winner70.037 %
58.427 %
Vals AI
Source details
Data as of: 06/04/2026
Vibe Code Bench v1.1Overall
Test details
No documented difference in the test setupVersion: 1.1Metric: accuracyScoring: Higher is betterClaude Opus 4.8: Harness: OpenHands
GPT-5.4: Snapshot: gpt-5.4-2026-03-05, Harness: OpenHands
Winner82.725 %
67.421 %
Vals AI
Source details
Data as of: 09/27/2026

Key to the marks:better valuebetter, but not conclusivetie

Our model tests

Our tests

Compare how the models respond to the same prompt. Each test shows the latest attempt, with no subsequent fixes to the generated code. Earlier runs remain available in the test details. These results do not contribute to an overall score.

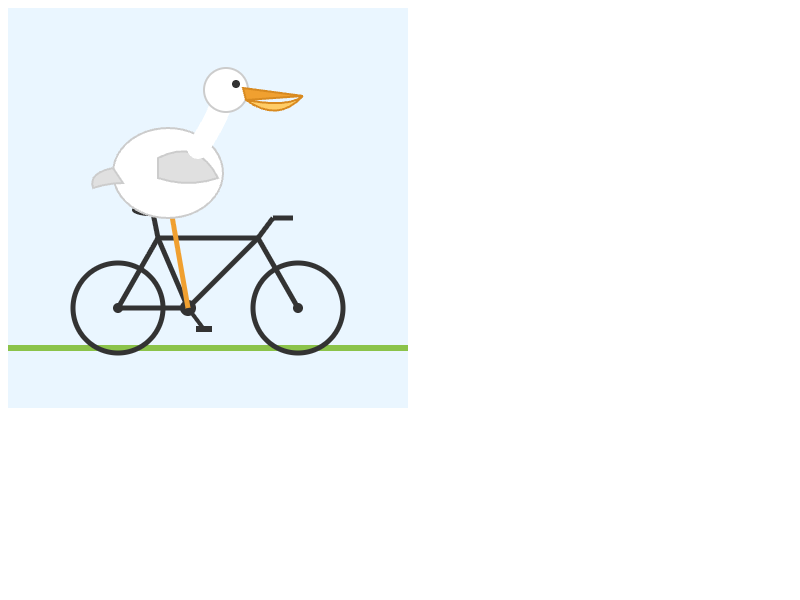
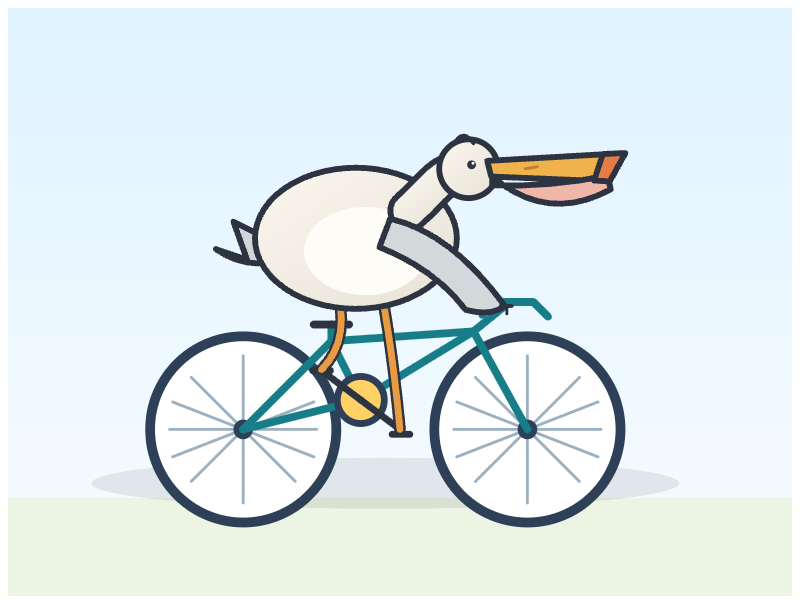
Pelican on a bicycle

A community classic for free-form SVG drawing.

Claude Opus 4.8

Claude Opus 4.8: Pelican on a bicycle
A community classic for free-form SVG drawing.

Reasoning (requested): high

Current attempt
Run date
1 Oct 2026
API provider
openrouter
Requested API model
anthropic/claude-opus-4.8
API model reported in response
anthropic/claude-opus-4.8
Reasoning setting
high
Pinned endpoint
Anthropic | anthropic/claude-4.8-opus-20260528
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
18 s

Visually reviewed. This individual test does not establish overall model quality.

GPT-5.4

GPT-5.4: Pelican on a bicycle
A community classic for free-form SVG drawing.

Reasoning (requested): high

Current attempt
Run date
1 Oct 2026
API provider
openrouter
Requested API model
openai/gpt-5.4
API model reported in response
openai/gpt-5.4
Reasoning setting
high
Pinned endpoint
OpenAI | openai/gpt-5.4-20260305
Temperature
Provider default
Token limit including reasoning
8,192 tokens
Test protocol
community-visual-tests-v1
Technical checks
Passed, not a quality rating
Response time
116.8 s

Visually reviewed. This individual test does not establish overall model quality.

Earlier attempts (1)
  • 7 Sept 2026API request failedReasoning setting: high
Prompt and test conditions

Generate an SVG of a pelican riding a bicycle

Token limit including reasoning: 8,192 tokens

Task origin (Simon Willison)

How to read this comparison

Winning one benchmark is not an overall verdict

Your workload, budget, and required context length matter most. A coding benchmark says little about visual understanding or agent performance.

The standard price table uses direct developer rates. The provider comparison labels OpenRouter endpoints, regions, and special tariffs separately.

Every result links to its measurement source and retrieval date. Labels distinguish vendor reports, official benchmark leaderboards, and independent evaluations. Disputed or archived results are excluded.

More matchups

Compare Claude Opus 4.8 and GPT-5.4 with other leading models using the same data and benchmark logic.

View the complete LLM comparison